

The Document Extractor node converts uploaded files into text that LLMs can process. Since language models can’t directly read document formats like PDF or DOCX, this node serves as the essential bridge between file uploads and AI analysis.
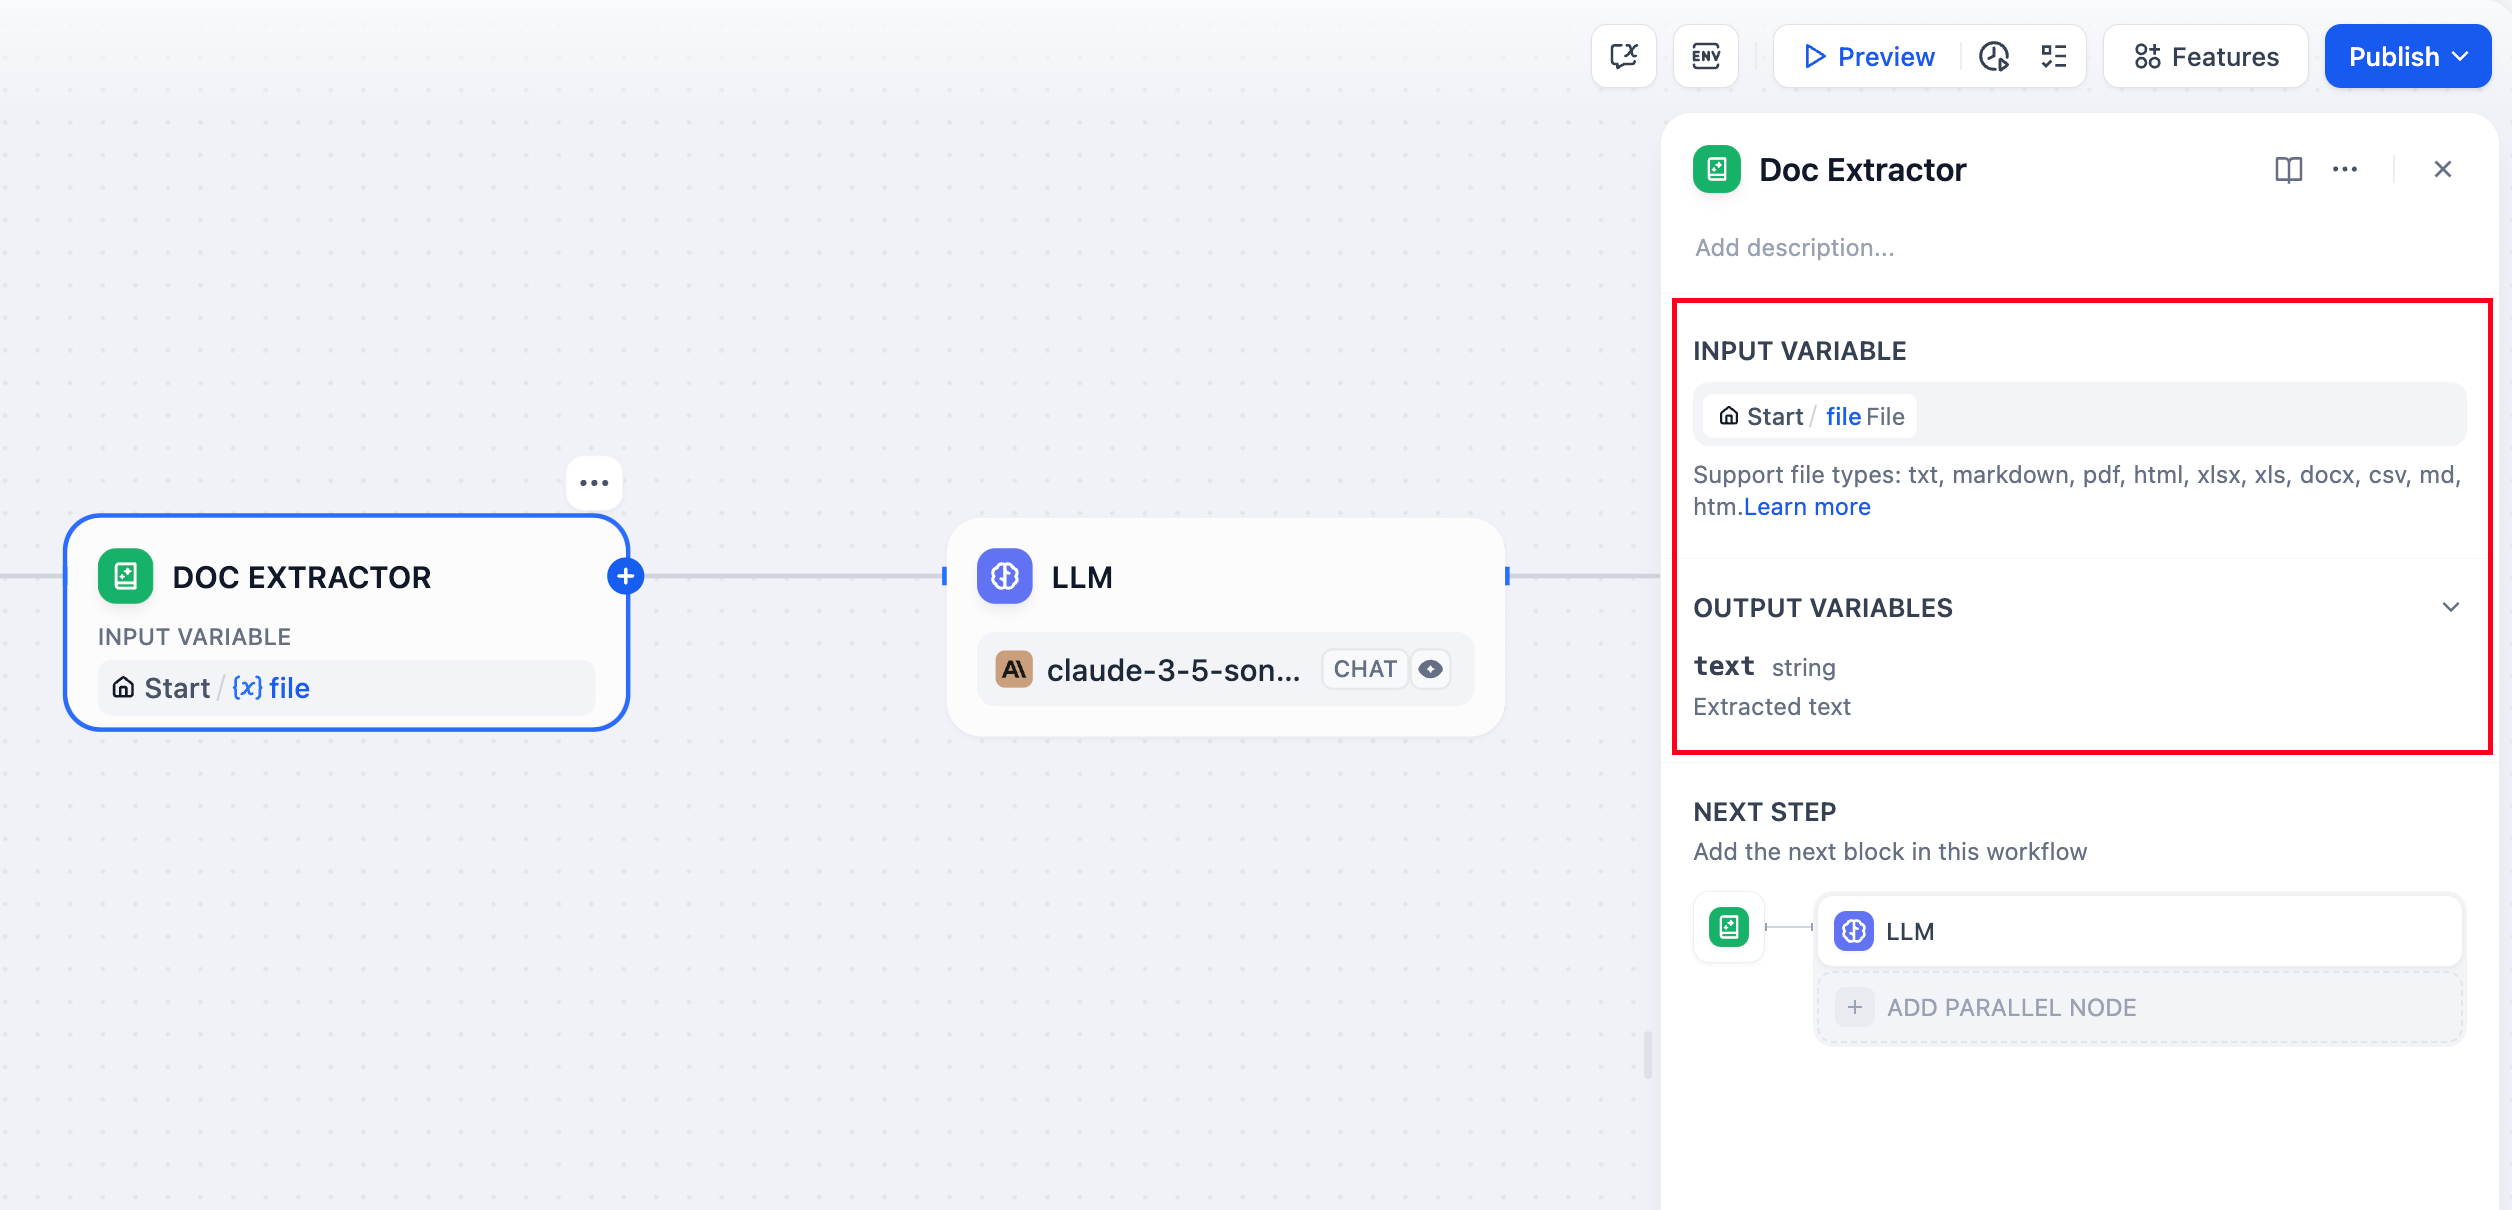
Supported File Types#
The node handles most text-based document formats:
Text Documents - TXT, Markdown, HTML files with direct text content
Office Documents - DOCX files from Microsoft Word and compatible applications
PDF Documents - Text-based PDFs
Office Files - DOCX files parse directly, with tables converted to Markdown. DOC and ODT files are also supported.
Spreadsheets - Excel (.xls/.xlsx) and CSV files converted to Markdown tables
Presentations - PowerPoint (.ppt/.pptx) files
Email Formats - EML and MSG files for email content extraction
Specialized Formats - EPUB books, VTT subtitles, JSON/YAML data, and Properties files
Files containing primarily binary content like images, audio, or video require specialized processing tools or external services.
Input and Output#
Input Configuration#
Configure the node to accept either:
Single File input from a file variable (typically from the Start node)
Multiple Files as an array for batch document processing
Output Structure#
The node outputs extracted text content:
- Single file input produces a
stringcontaining the extracted text - Multiple file input produces an
array[string]with each file’s content
The output variable is named text and contains the raw text content ready for downstream processing.
Implementation Example#
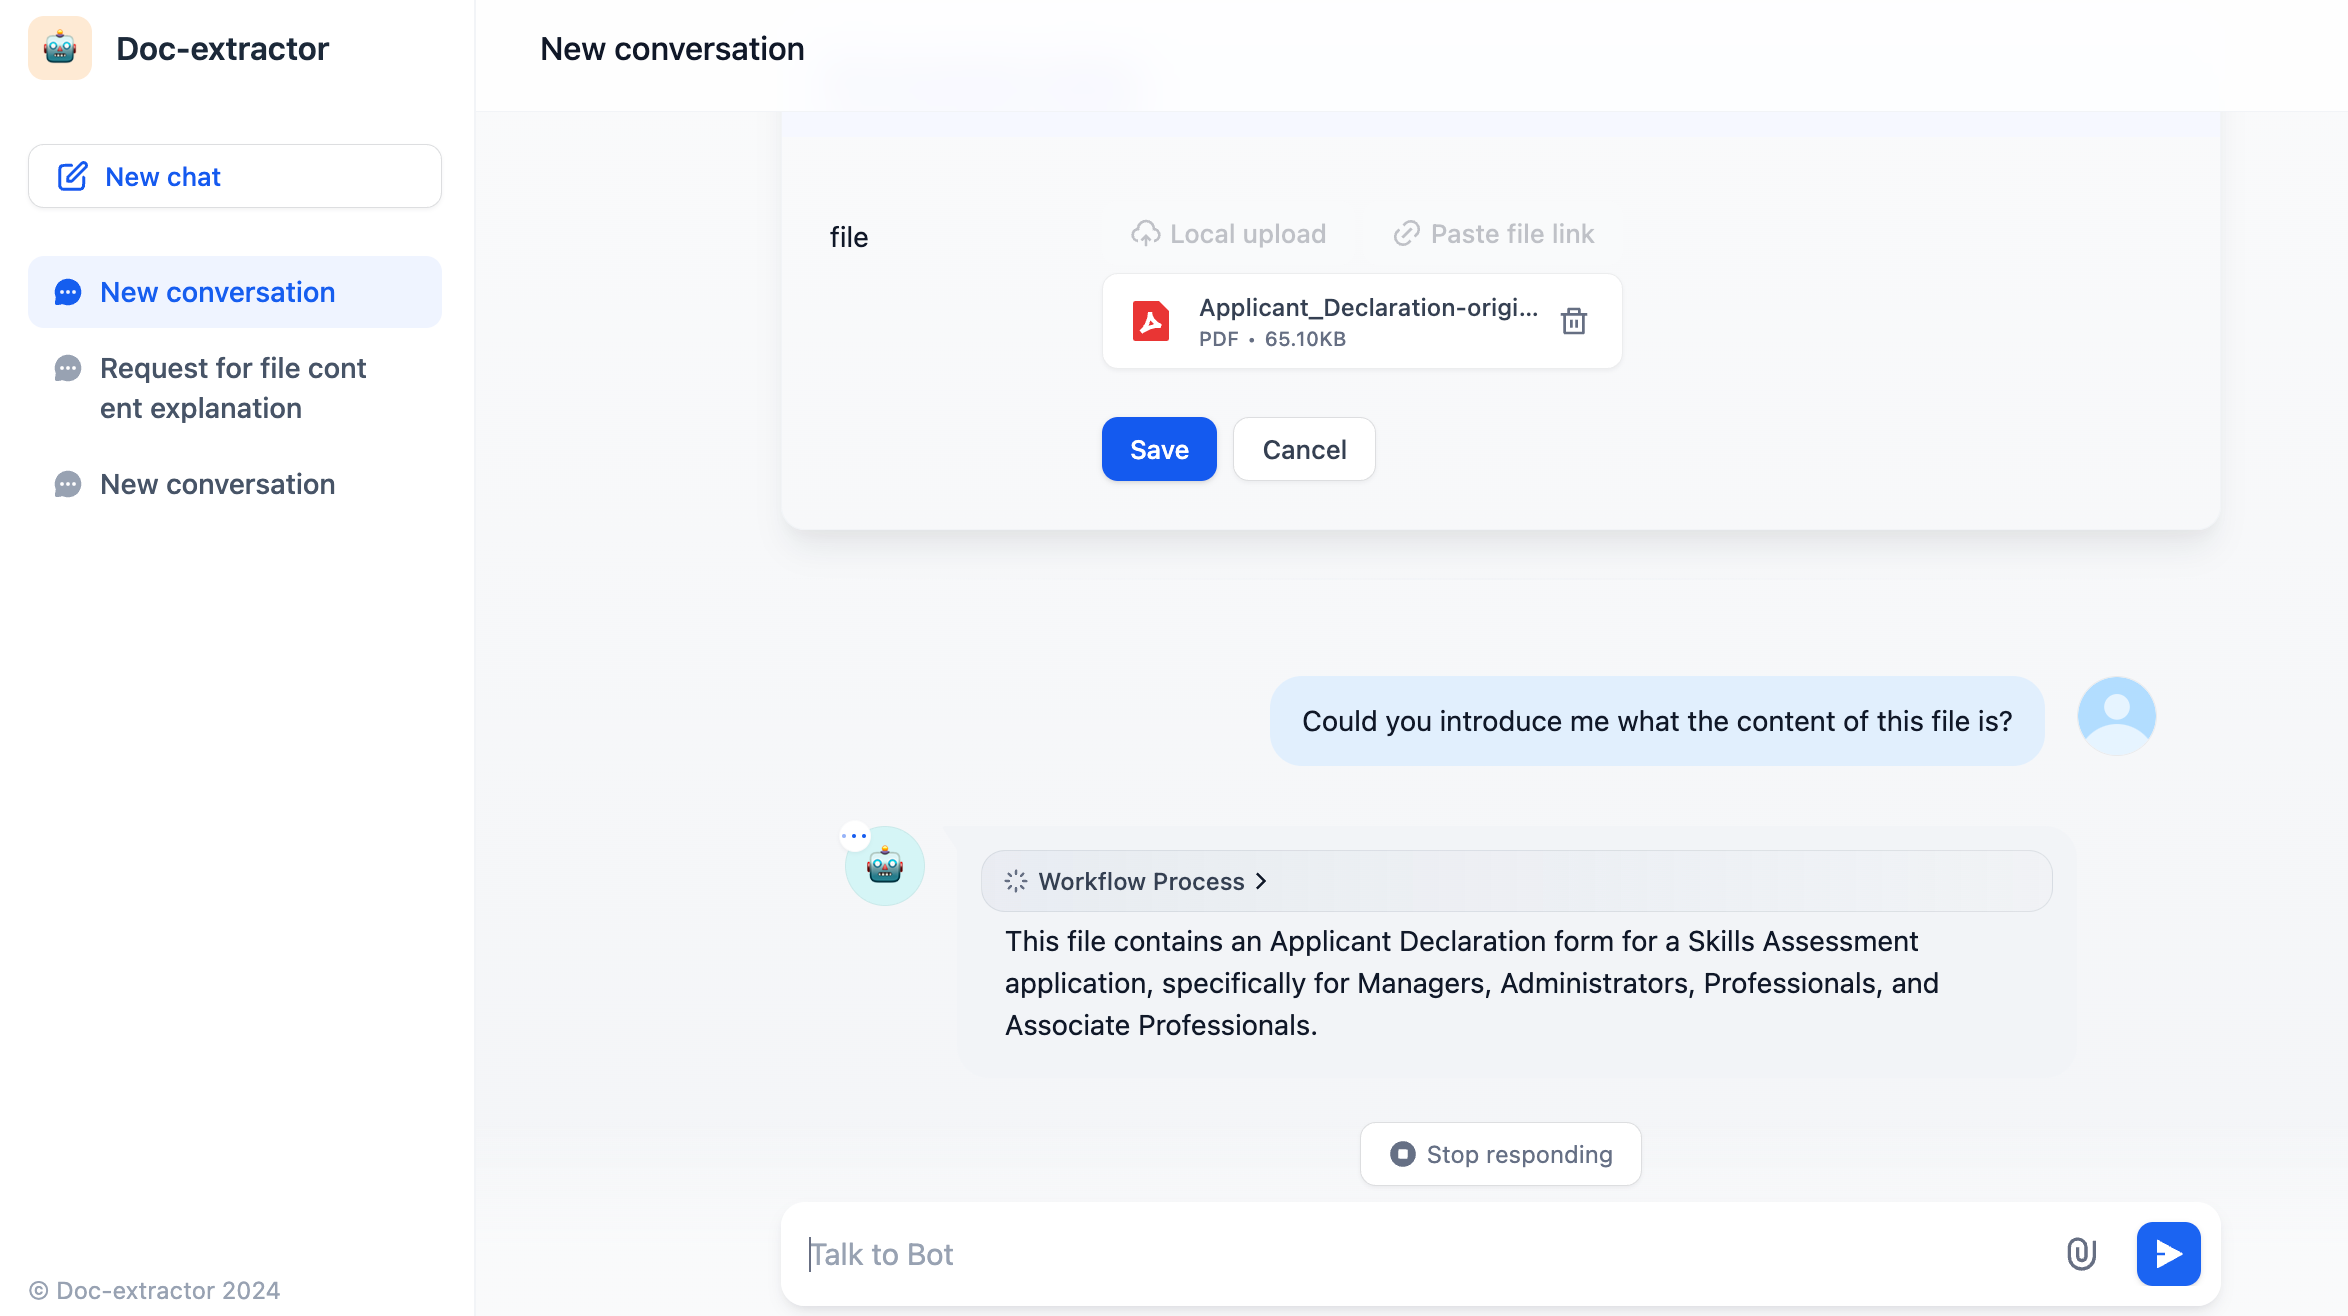
Here’s a complete document Q&A workflow using the Document Extractor:
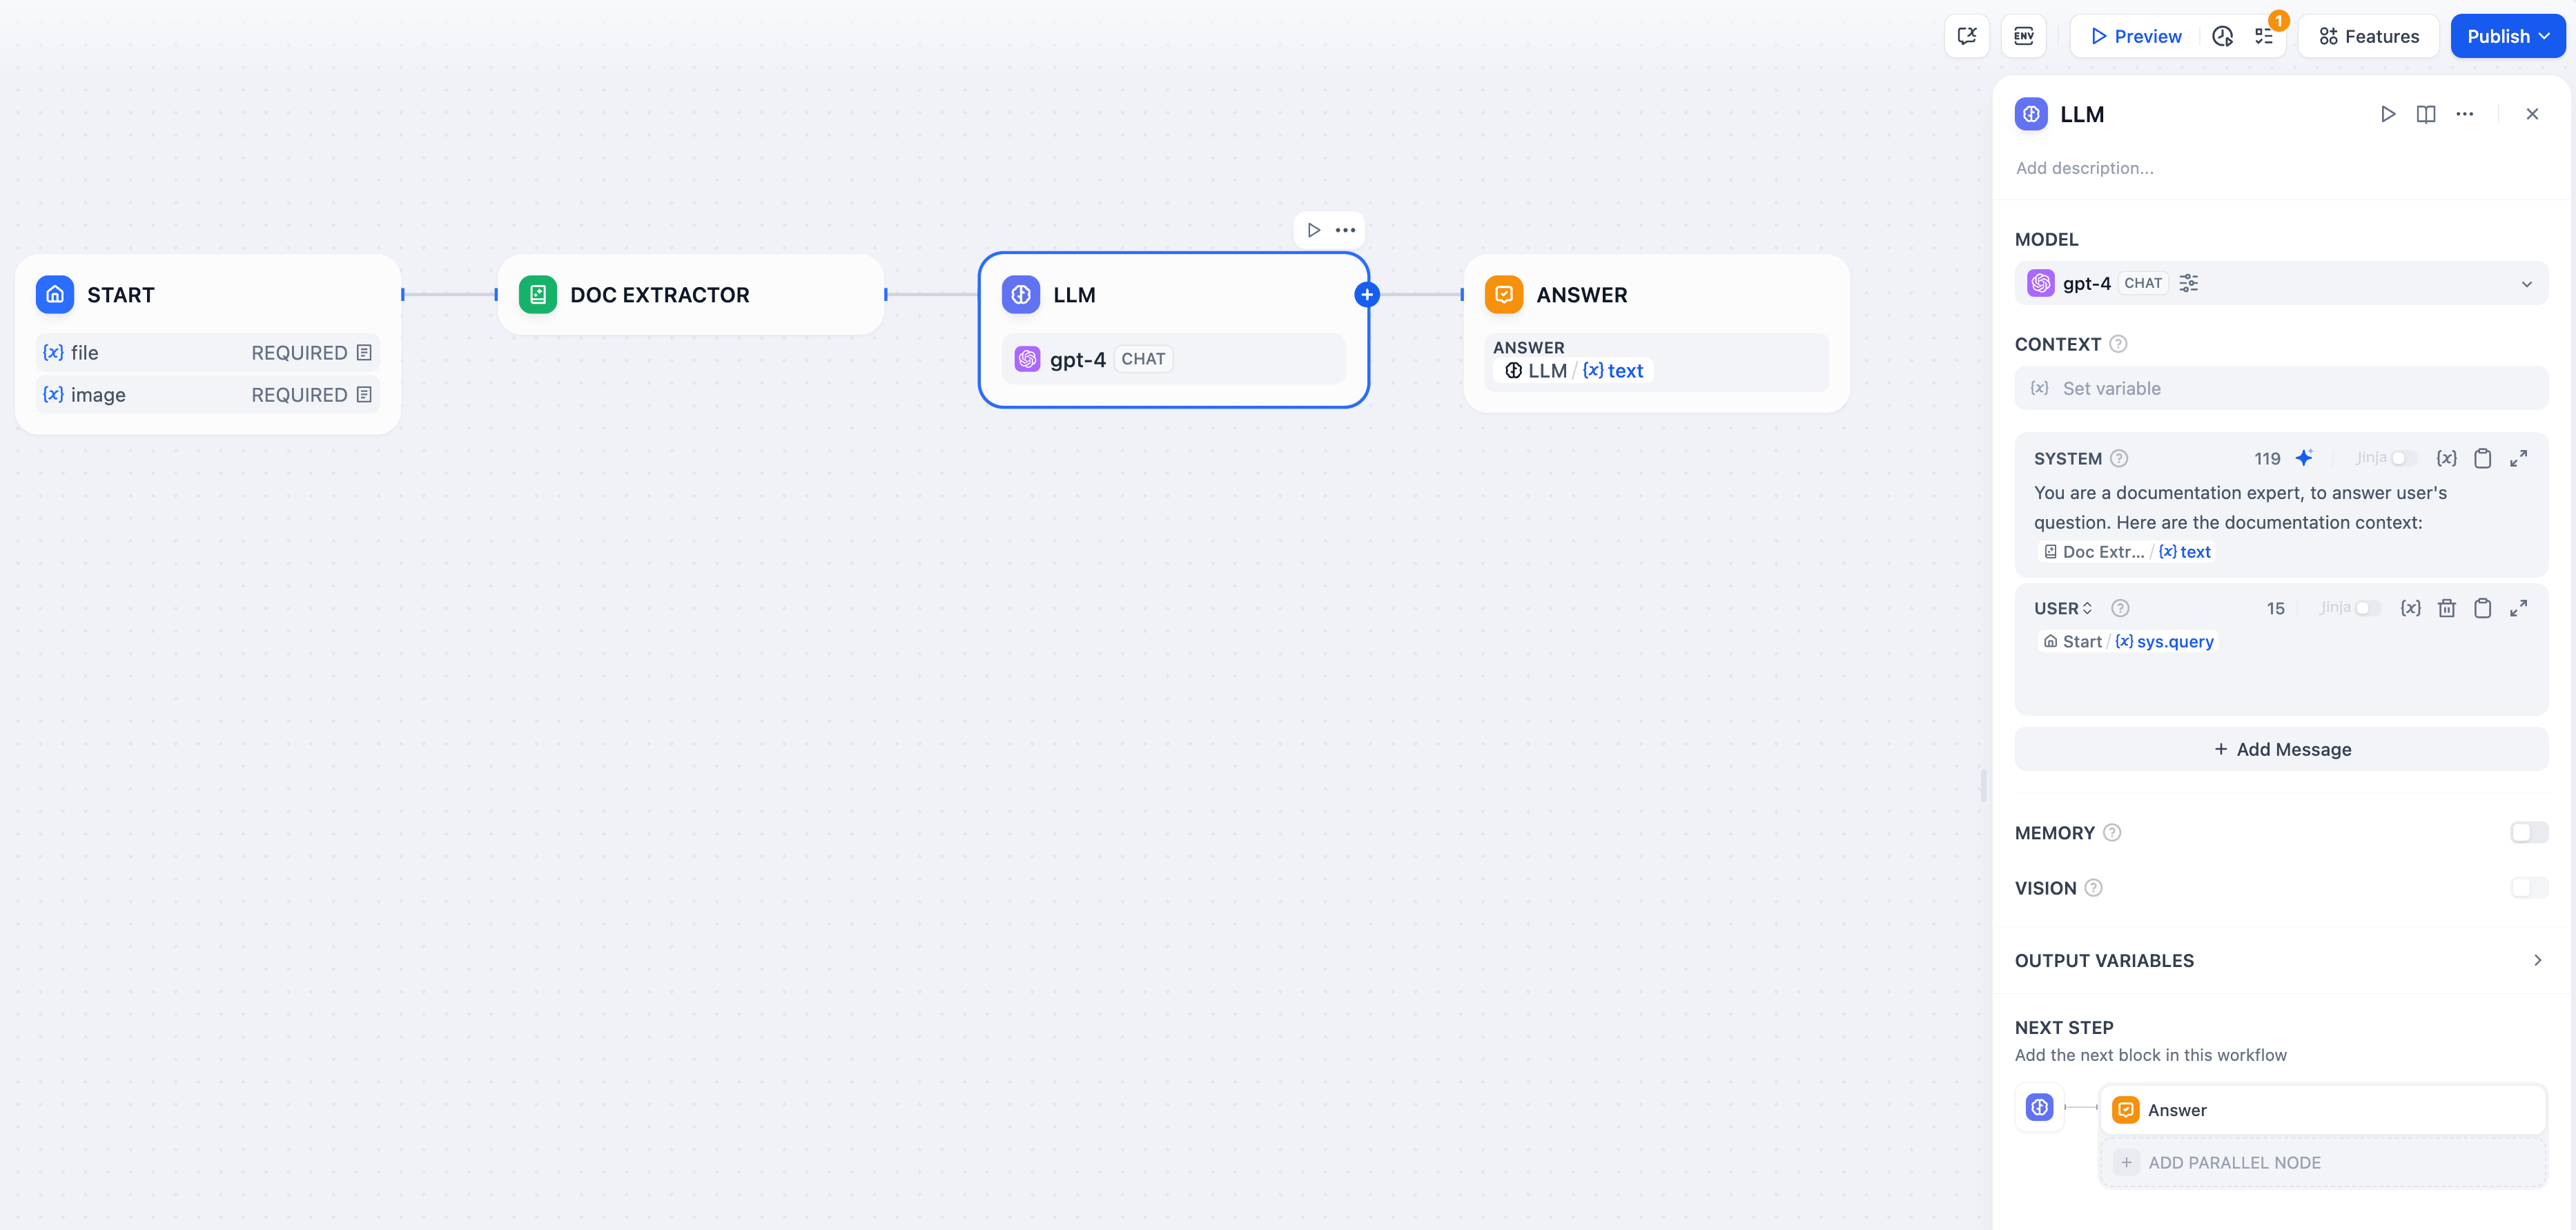
Workflow Setup#
File Upload Configuration - Enable file input in your Start node to accept document uploads from users.
Text Extraction - Connect the Document Extractor to process uploaded files and extract their text content.
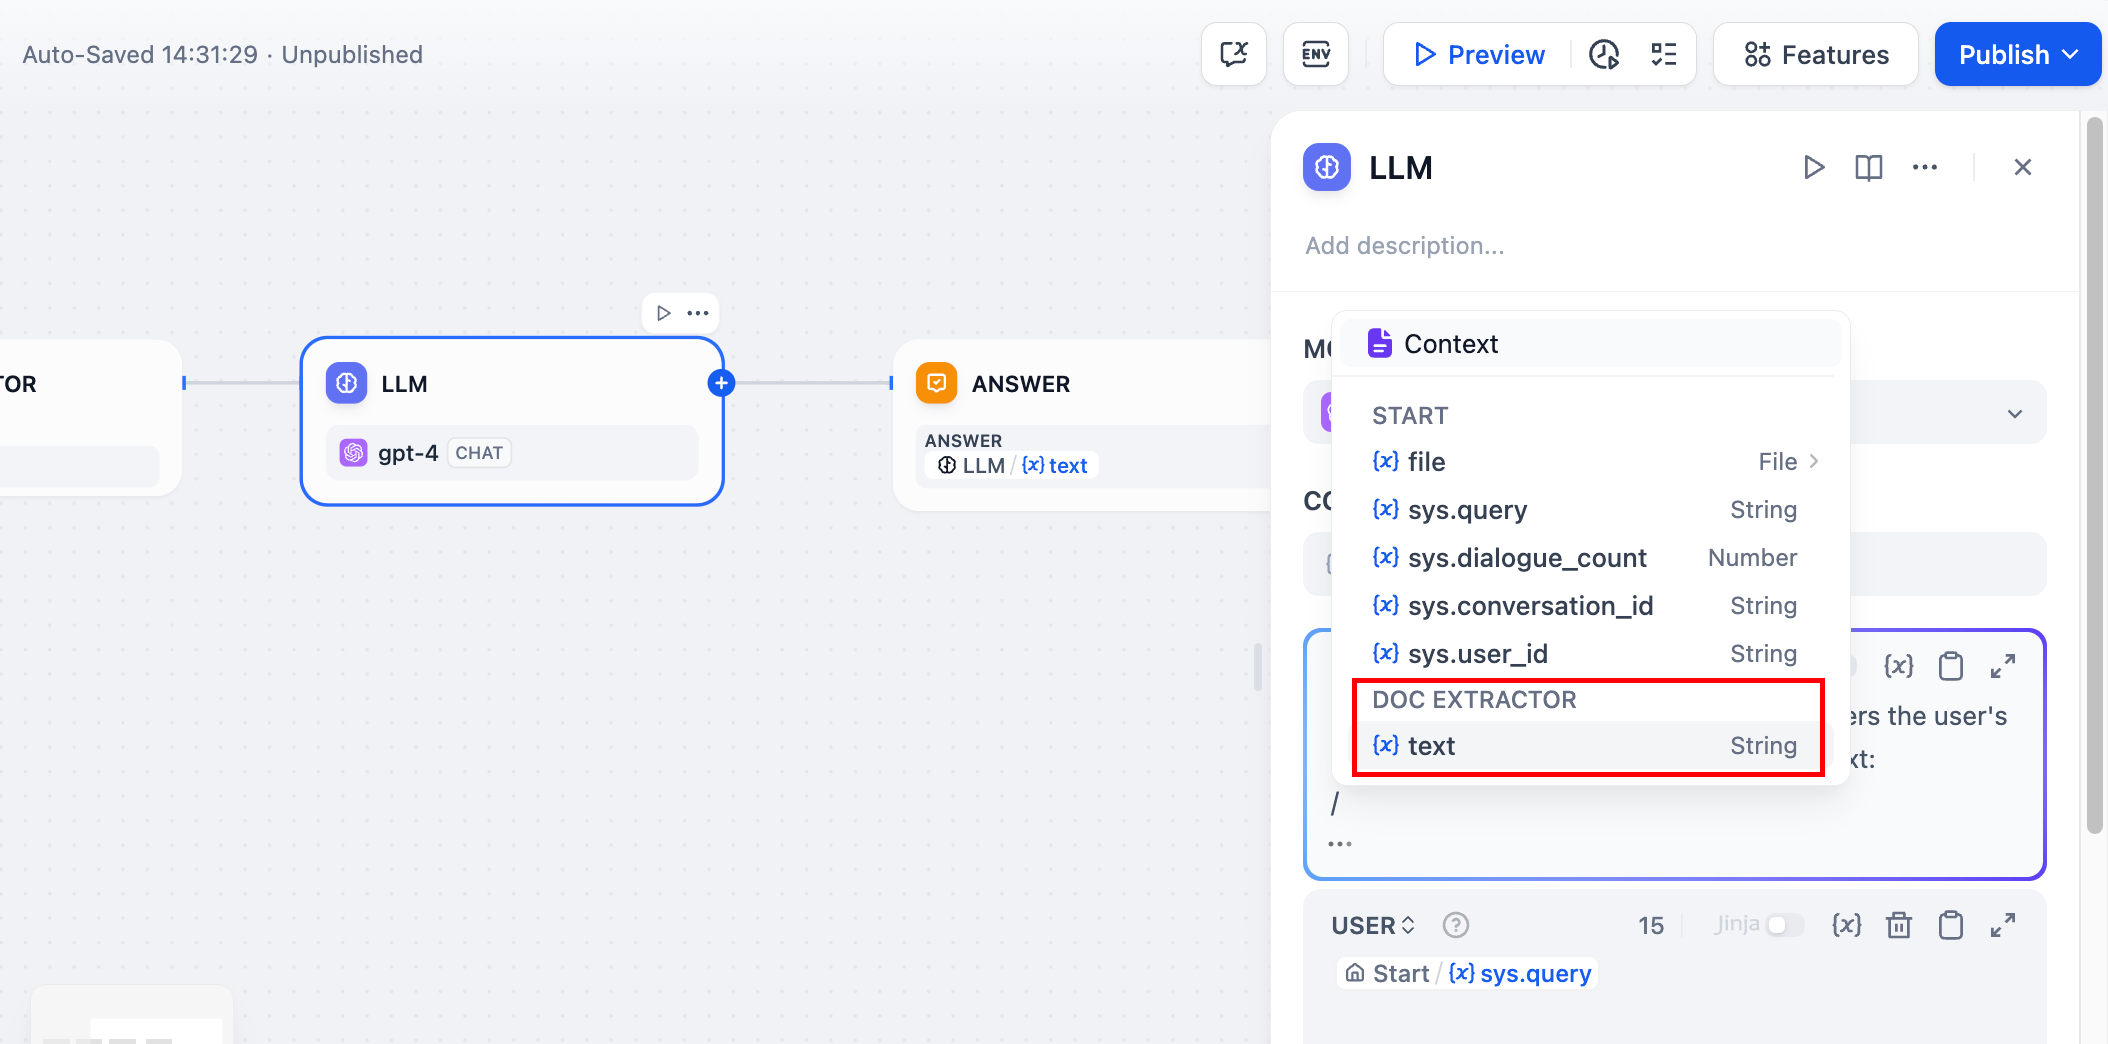
AI Processing - Use the extracted text in LLM prompts for analysis, summarization, or question answering.
Processing Considerations#
The Document Extractor uses specialized parsing libraries optimized for different file formats. It preserves text structure and formatting where possible, making extracted content more useful for LLM processing.
File Format Processing#
Encoding Detection - Uses chardet library to automatically detect file encoding with UTF-8 fallback for text-based files
Table Conversion - Excel and CSV data becomes Markdown tables for better LLM comprehension
Document Structure - DOCX files maintain paragraph and table ordering with proper table-to-Markdown conversion
Multi-line Content - VTT subtitle files merge consecutive utterances by the same speaker
For very large documents, consider the LLM’s context limits and implement chunking strategies if needed. The extracted text maintains the original document’s logical structure to preserve meaning and context.