

An Agent Strategy Plugin gives an LLM the reasoning and decision-making logic to choose tools, call them, and handle their results, so it can solve problems autonomously.
This guide walks through building a Function Calling strategy that lets the model fetch the current time on its own.
Prerequisites#
- Dify plugin scaffolding tool
- Python environment (version 3.12)
For details on preparing the plugin development tool, see CLI.
Run dify version in your terminal to confirm that the scaffolding tool is installed.
1. Initialize the Plugin Template#
Run the following command to create a development template for your Agent plugin:
dify plugin initFollow the on-screen prompts; the comments below explain each choice.
➜ Dify Plugins Developing dify plugin initEdit profile of the pluginPlugin name (press Enter to next step): # Enter the plugin nameAuthor (press Enter to next step): Author name # Enter the plugin authorDescription (press Enter to next step): Description # Enter the plugin description---Select the language you want to use for plugin development, and press Enter to conBTW, you need Python 3.12+ to develop the Plugin if you choose Python.-> python # Select Python environment go (not supported yet)---Based on the ability you want to extend, we have divided the Plugin into four type- Tool: It's a tool provider, but not only limited to tools, you can implement an- Model: Just a model provider, extending others is not allowed.- Extension: Other times, you may only need a simple http service to extend the fu- Agent Strategy: Implement your own logics here, just by focusing on Agent itselfWhat's more, we have provided the template for you, you can choose one of them b tool-> agent-strategy # Select Agent strategy template llm text-embedding---Configure the permissions of the plugin, use up and down to navigate, tab to selBackwards Invocation:Tools: Enabled: [✔] You can invoke tools inside Dify if it's enabled # Enabled by defaultModels: Enabled: [✔] You can invoke models inside Dify if it's enabled # Enabled by default LLM: [✔] You can invoke LLM models inside Dify if it's enabled # Enabled by default Text Embedding: [✘] You can invoke text embedding models inside Dify if it' Rerank: [✘] You can invoke rerank models inside Dify if it's enabled...Initialization creates a folder with everything you need for plugin development:
├── GUIDE.md # User guide and documentation├── PRIVACY.md # Privacy policy and data handling guidelines├── README.md # Project overview and setup instructions├── _assets/ # Static assets directory│ └── icon.svg # Agent strategy provider icon/logo├── main.py # Main application entry point├── manifest.yaml # Basic plugin configuration├── provider/ # Provider configurations directory│ └── basic_agent.yaml # Your agent provider settings├── requirements.txt # Python dependencies list└── strategies/ # Strategy implementation directory ├── basic_agent.py # Basic agent strategy implementation └── basic_agent.yaml # Basic agent strategy configurationAll key functionality for this plugin is in the strategies/ directory.
2. Develop the Plugin#
Agent Strategy Plugin development revolves around two files:
- Plugin Declaration:
strategies/basic_agent.yaml - Plugin Implementation:
strategies/basic_agent.py
2.1 Define Parameters#
Start by declaring the plugin’s parameters in strategies/basic_agent.yaml. These parameters power the plugin’s core features, such as calling an LLM or using tools.
We recommend starting with these four parameters:
model: The large language model to call (e.g., GPT-4, GPT-4o-mini).tools: A list of tools that enhance your plugin’s functionality.query: The user input or prompt content sent to the model.maximum_iterations: The maximum iteration count, which prevents excessive computation.
Example:
identity: name: basic_agent # the name of the agent_strategy author: novice # the author of the agent_strategy label: en_US: BasicAgent # the English label of the agent_strategydescription: en_US: BasicAgent # the English description of the agent_strategyparameters: - name: model # the name of the model parameter type: model-selector # model-type scope: tool-call&llm # the scope of the parameter required: true label: en_US: Model zh_Hans: 模型 pt_BR: Model - name: tools # the name of the tools parameter type: array[tools] # the type of tool parameter required: true label: en_US: Tools list zh_Hans: 工具列表 pt_BR: Tools list - name: query # the name of the query parameter type: string # the type of query parameter required: true label: en_US: Query zh_Hans: 查询 pt_BR: Query - name: maximum_iterations type: number required: false default: 5 label: en_US: Maxium Iterations zh_Hans: 最大迭代次数 pt_BR: Maxium Iterations max: 50 # if you set the max and min value, the display of the parameter will be a slider min: 1extra: python: source: strategies/basic_agent.pyDify automatically renders a configuration interface from these parameter declarations:
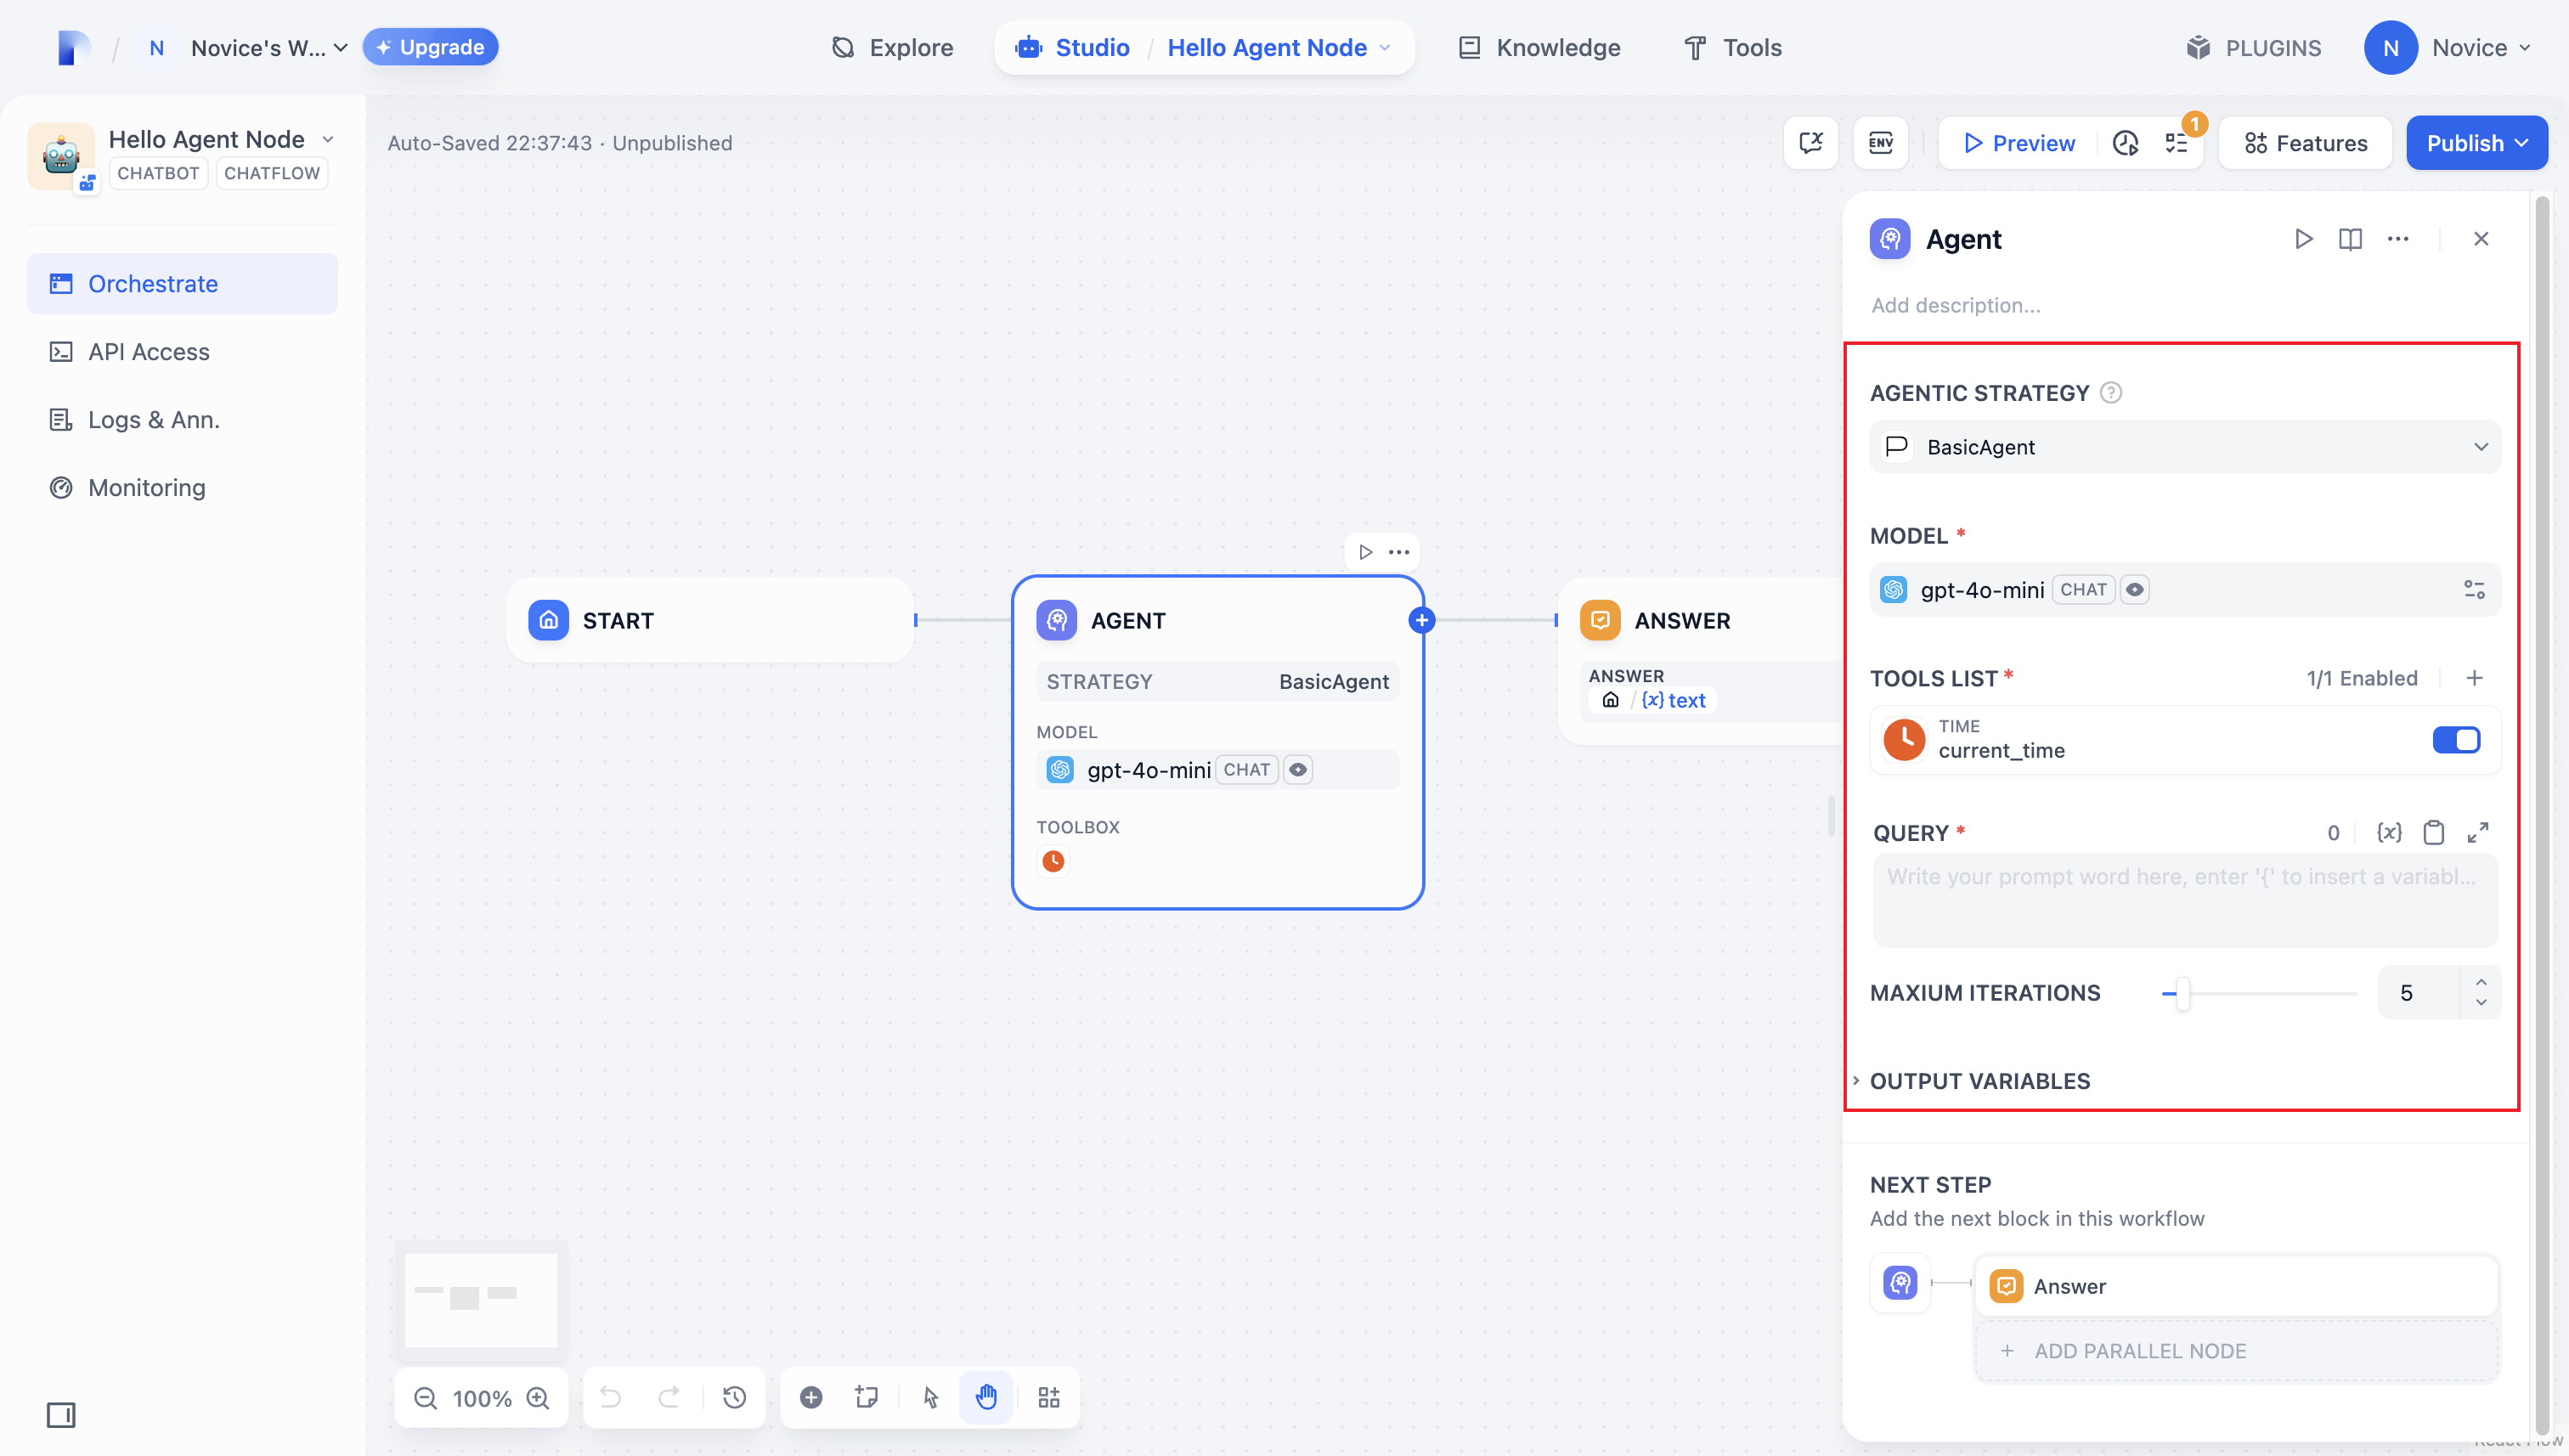
2.2 Retrieve Parameters and Execute#
When users fill out these fields, your plugin receives the submitted values. In strategies/basic_agent.py, define a Pydantic model that validates the incoming parameters:
from dify_plugin.entities.agent import AgentInvokeMessagefrom dify_plugin.interfaces.agent import AgentModelConfig, AgentStrategy, ToolEntityfrom pydantic import BaseModelclass BasicParams(BaseModel): maximum_iterations: int model: AgentModelConfig tools: list[ToolEntity] query: strThen parse the parameters in _invoke and run your strategy logic:
class BasicAgentAgentStrategy(AgentStrategy): def _invoke(self, parameters: dict[str, Any]) -> Generator[AgentInvokeMessage]: params = BasicParams(**parameters)3. Invoke the Model#
Invoking the model is central to an Agent strategy. Use session.model.llm.invoke() from the SDK to call an LLM for text generation, dialogue, and similar tasks.
For the LLM to drive tool calls, it must output structured arguments that match each tool’s interface—input the tool can accept, derived from the user’s instructions.
The method takes the following parameters:
modelprompt_messagestoolsstopstream
Method signature:
def invoke( self, model_config: LLMModelConfig, prompt_messages: list[PromptMessage], tools: list[PromptMessageTool] | None = None, stop: list[str] | None = None, stream: bool = True, ) -> Generator[LLMResultChunk, None, None] | LLMResult:...For the full implementation, see the Invoke Model tab in the sample code below.
With this in place, the plugin calls the LLM whenever a user enters a command, builds tool-invocation parameters from the model’s output, and lets the model dispatch the configured tools to complete complex tasks.
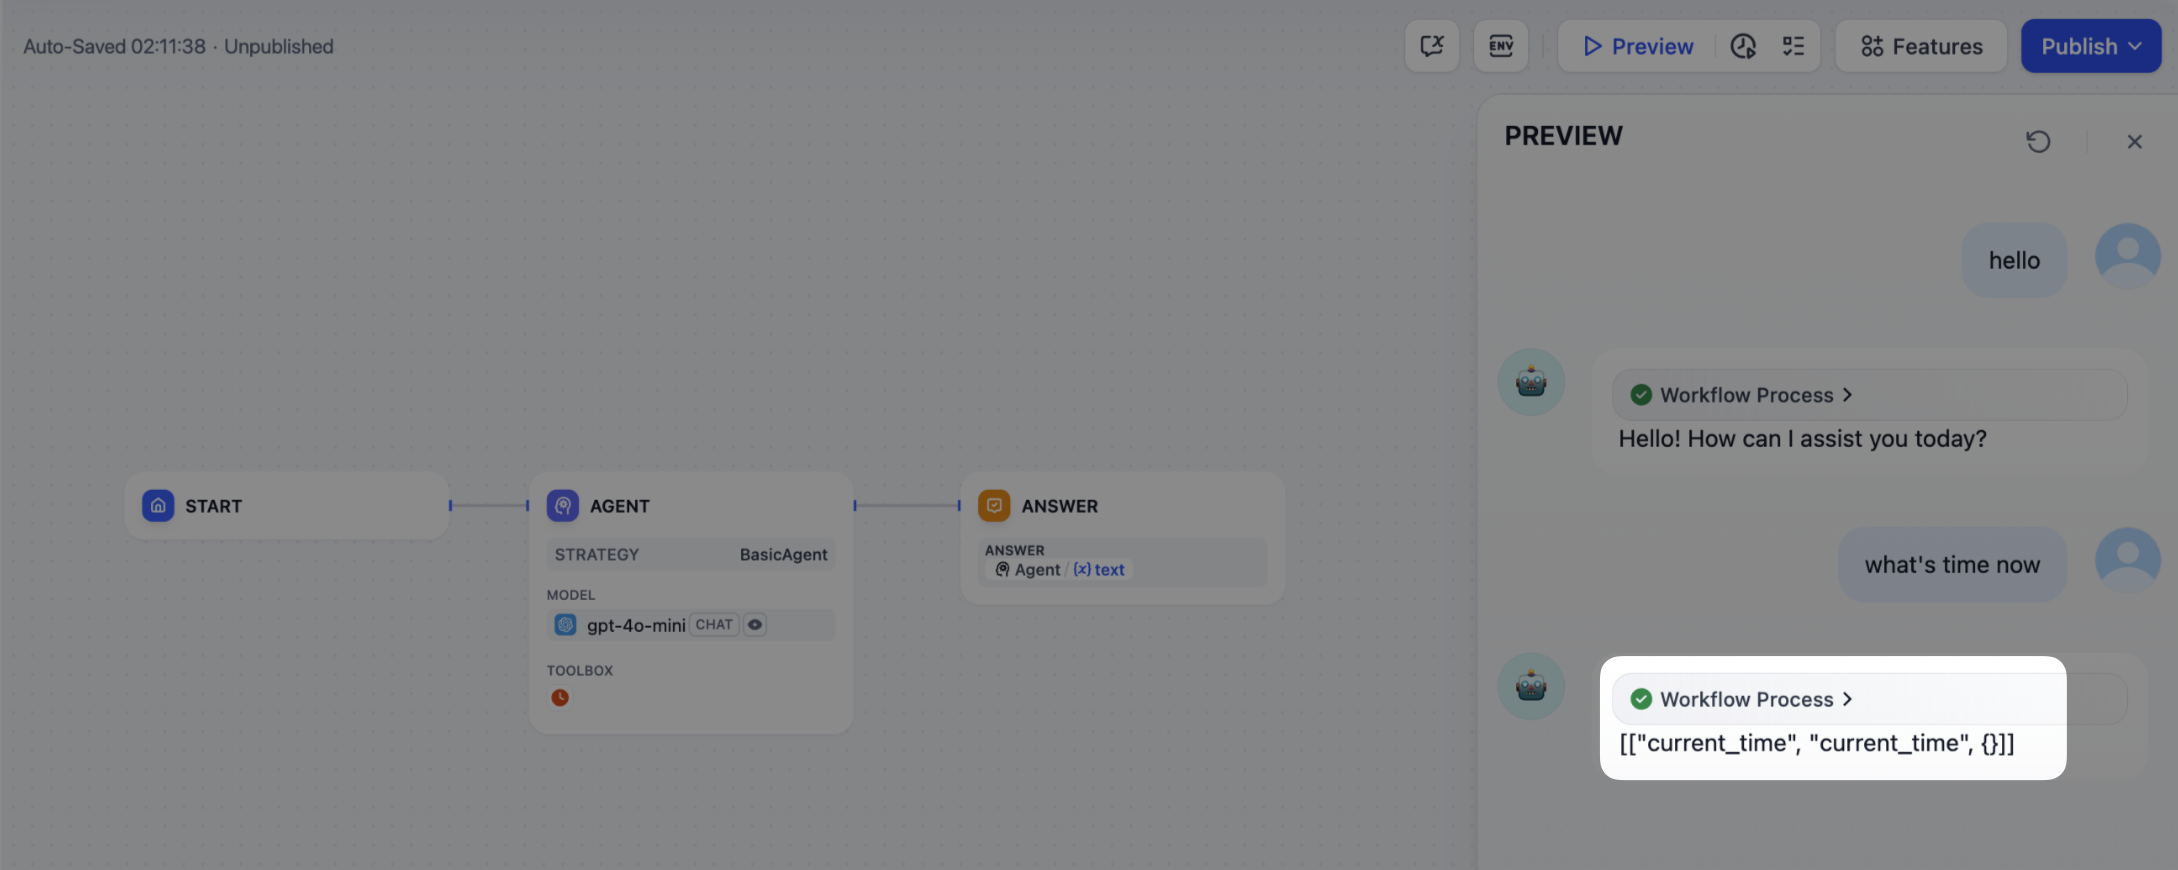
4. Invoke Tools#
Once the model has produced tool parameters, the plugin must actually call the tools. Use session.tool.invoke() to make those requests.
The method takes the following parameters:
providertool_nameparameters
Method signature:
def invoke( self, provider_type: ToolProviderType, provider: str, tool_name: str, parameters: dict[str, Any], ) -> Generator[ToolInvokeMessage, None, None]:...To let the LLM generate the tool-call parameters itself, feed the model’s extracted tool calls into your invocation code:
tool_instances = ( {tool.identity.name: tool for tool in params.tools} if params.tools else {})for tool_call_id, tool_call_name, tool_call_args in tool_calls: tool_instance = tool_instances[tool_call_name] self.session.tool.invoke( provider_type=ToolProviderType.BUILT_IN, provider=tool_instance.identity.provider, tool_name=tool_instance.identity.name, parameters={**tool_instance.runtime_parameters, **tool_call_args}, )Your plugin can now perform Function Calling automatically—for instance, retrieving the current time.
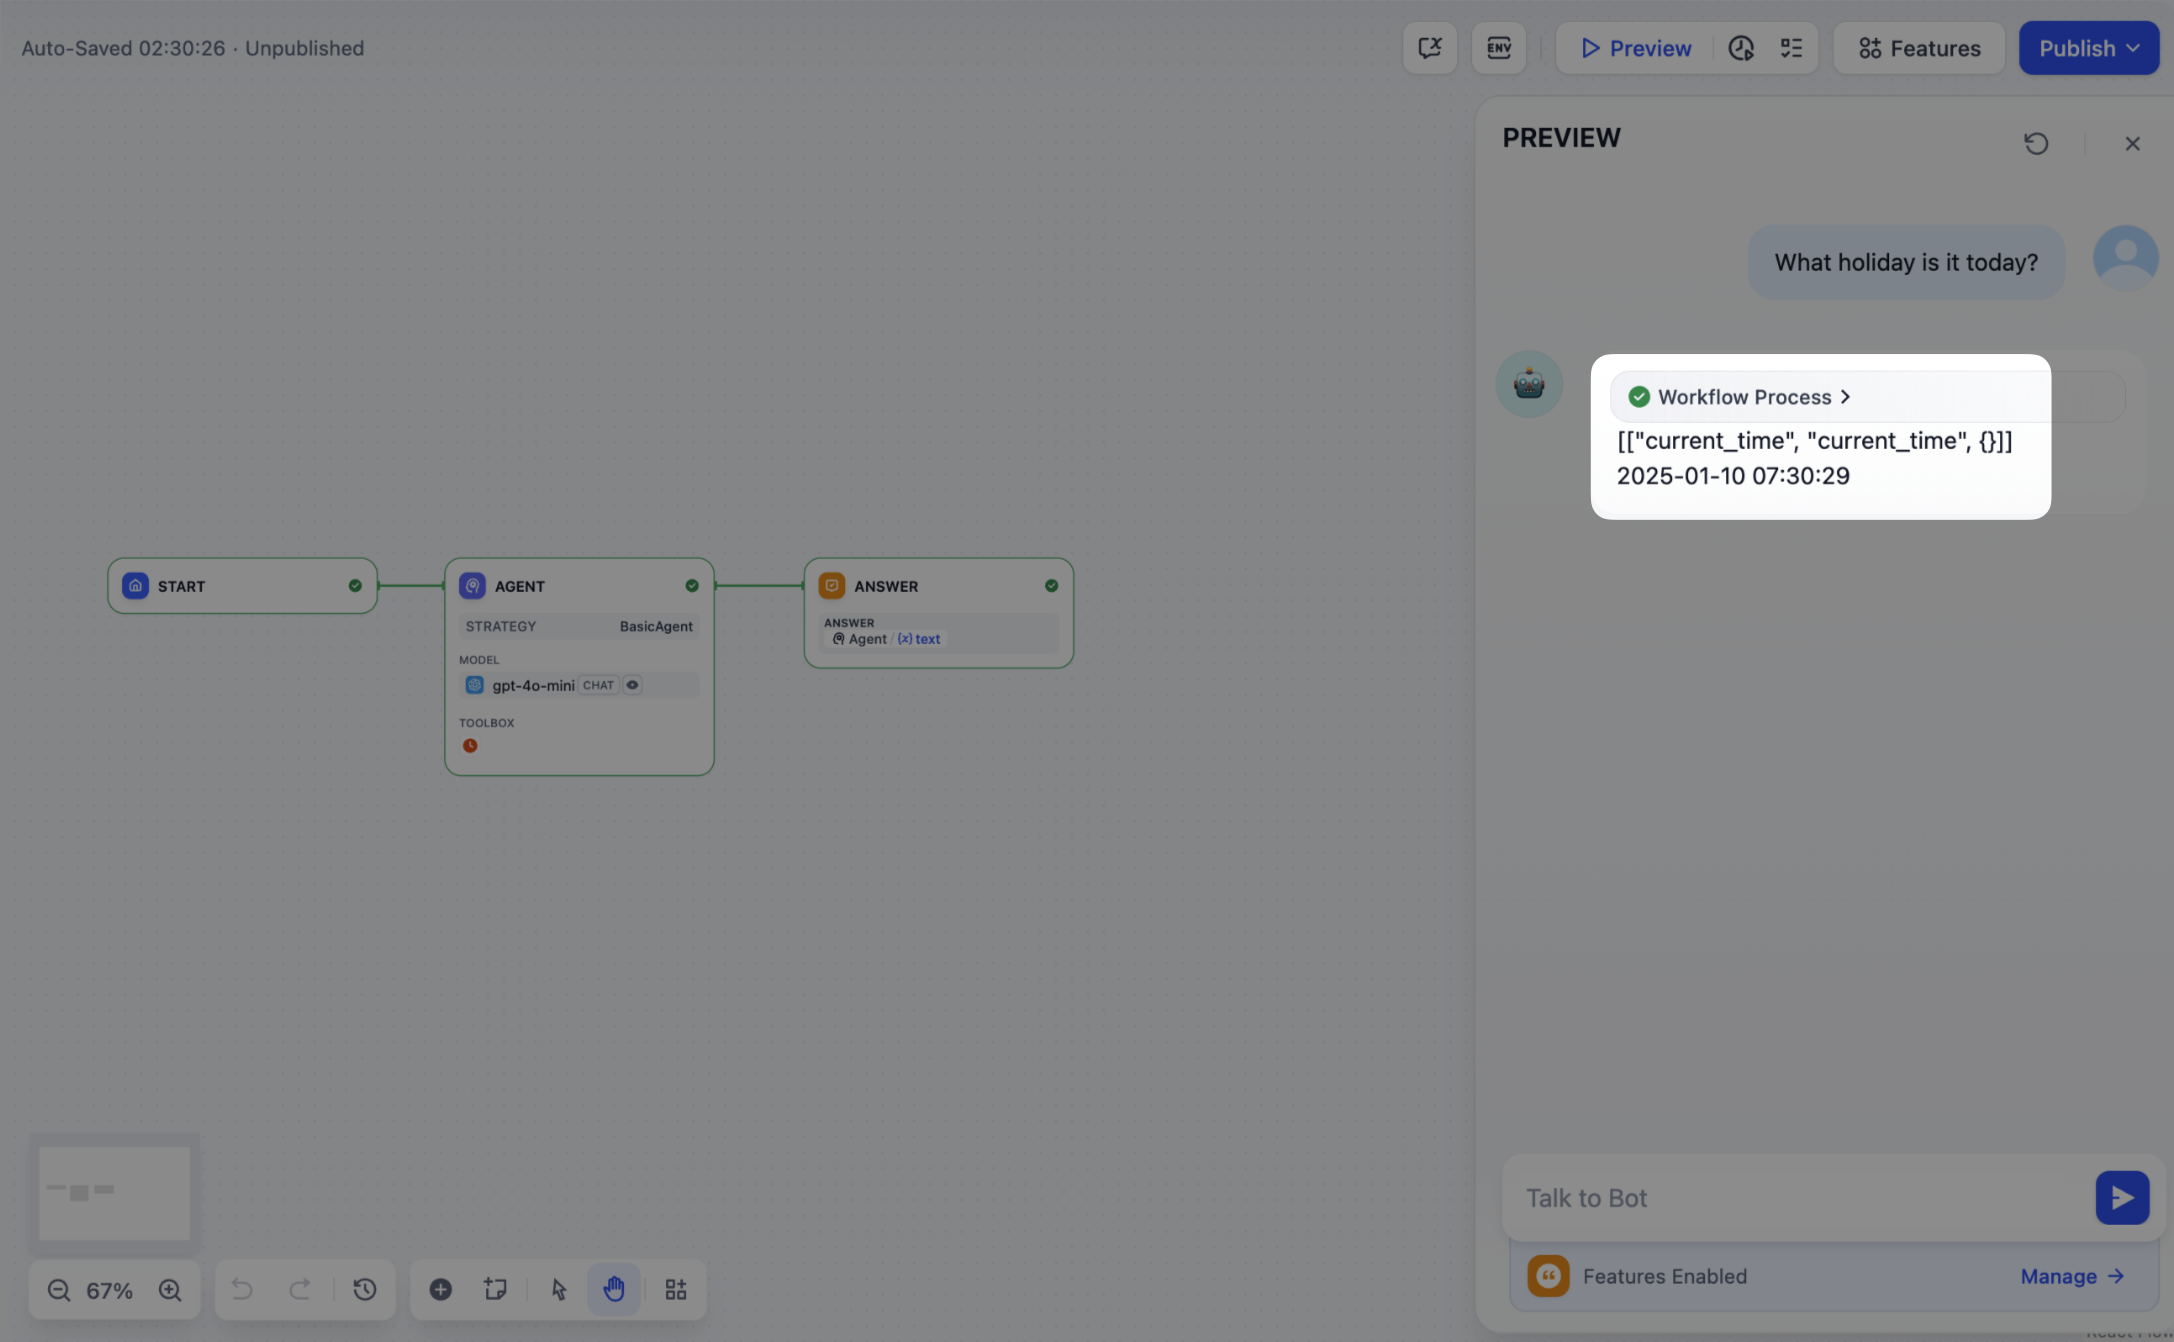
5. Create Logs#
Complex tasks usually take multiple steps, and you need to track each step’s result to analyze decisions and refine your strategy. The SDK’s create_log_message and finish_log_message let you record state before and after each call, which speeds up problem diagnosis.
For example:
- Log a “starting model call” message before calling the model to show execution progress.
- Log a “call succeeded” message once the model responds, so its output can be traced end to end.
model_log = self.create_log_message( label=f"{params.model.model} Thought", data={}, metadata={"start_at": model_started_at, "provider": params.model.provider}, status=ToolInvokeMessage.LogMessage.LogStatus.START, )yield model_logself.session.model.llm.invoke(...)yield self.finish_log_message( log=model_log, data={ "output": response, "tool_name": tool_call_names, "tool_input": tool_call_inputs, }, metadata={ "started_at": model_started_at, "finished_at": time.perf_counter(), "elapsed_time": time.perf_counter() - model_started_at, "provider": params.model.provider, },)Once set up, the workflow log shows the execution results:
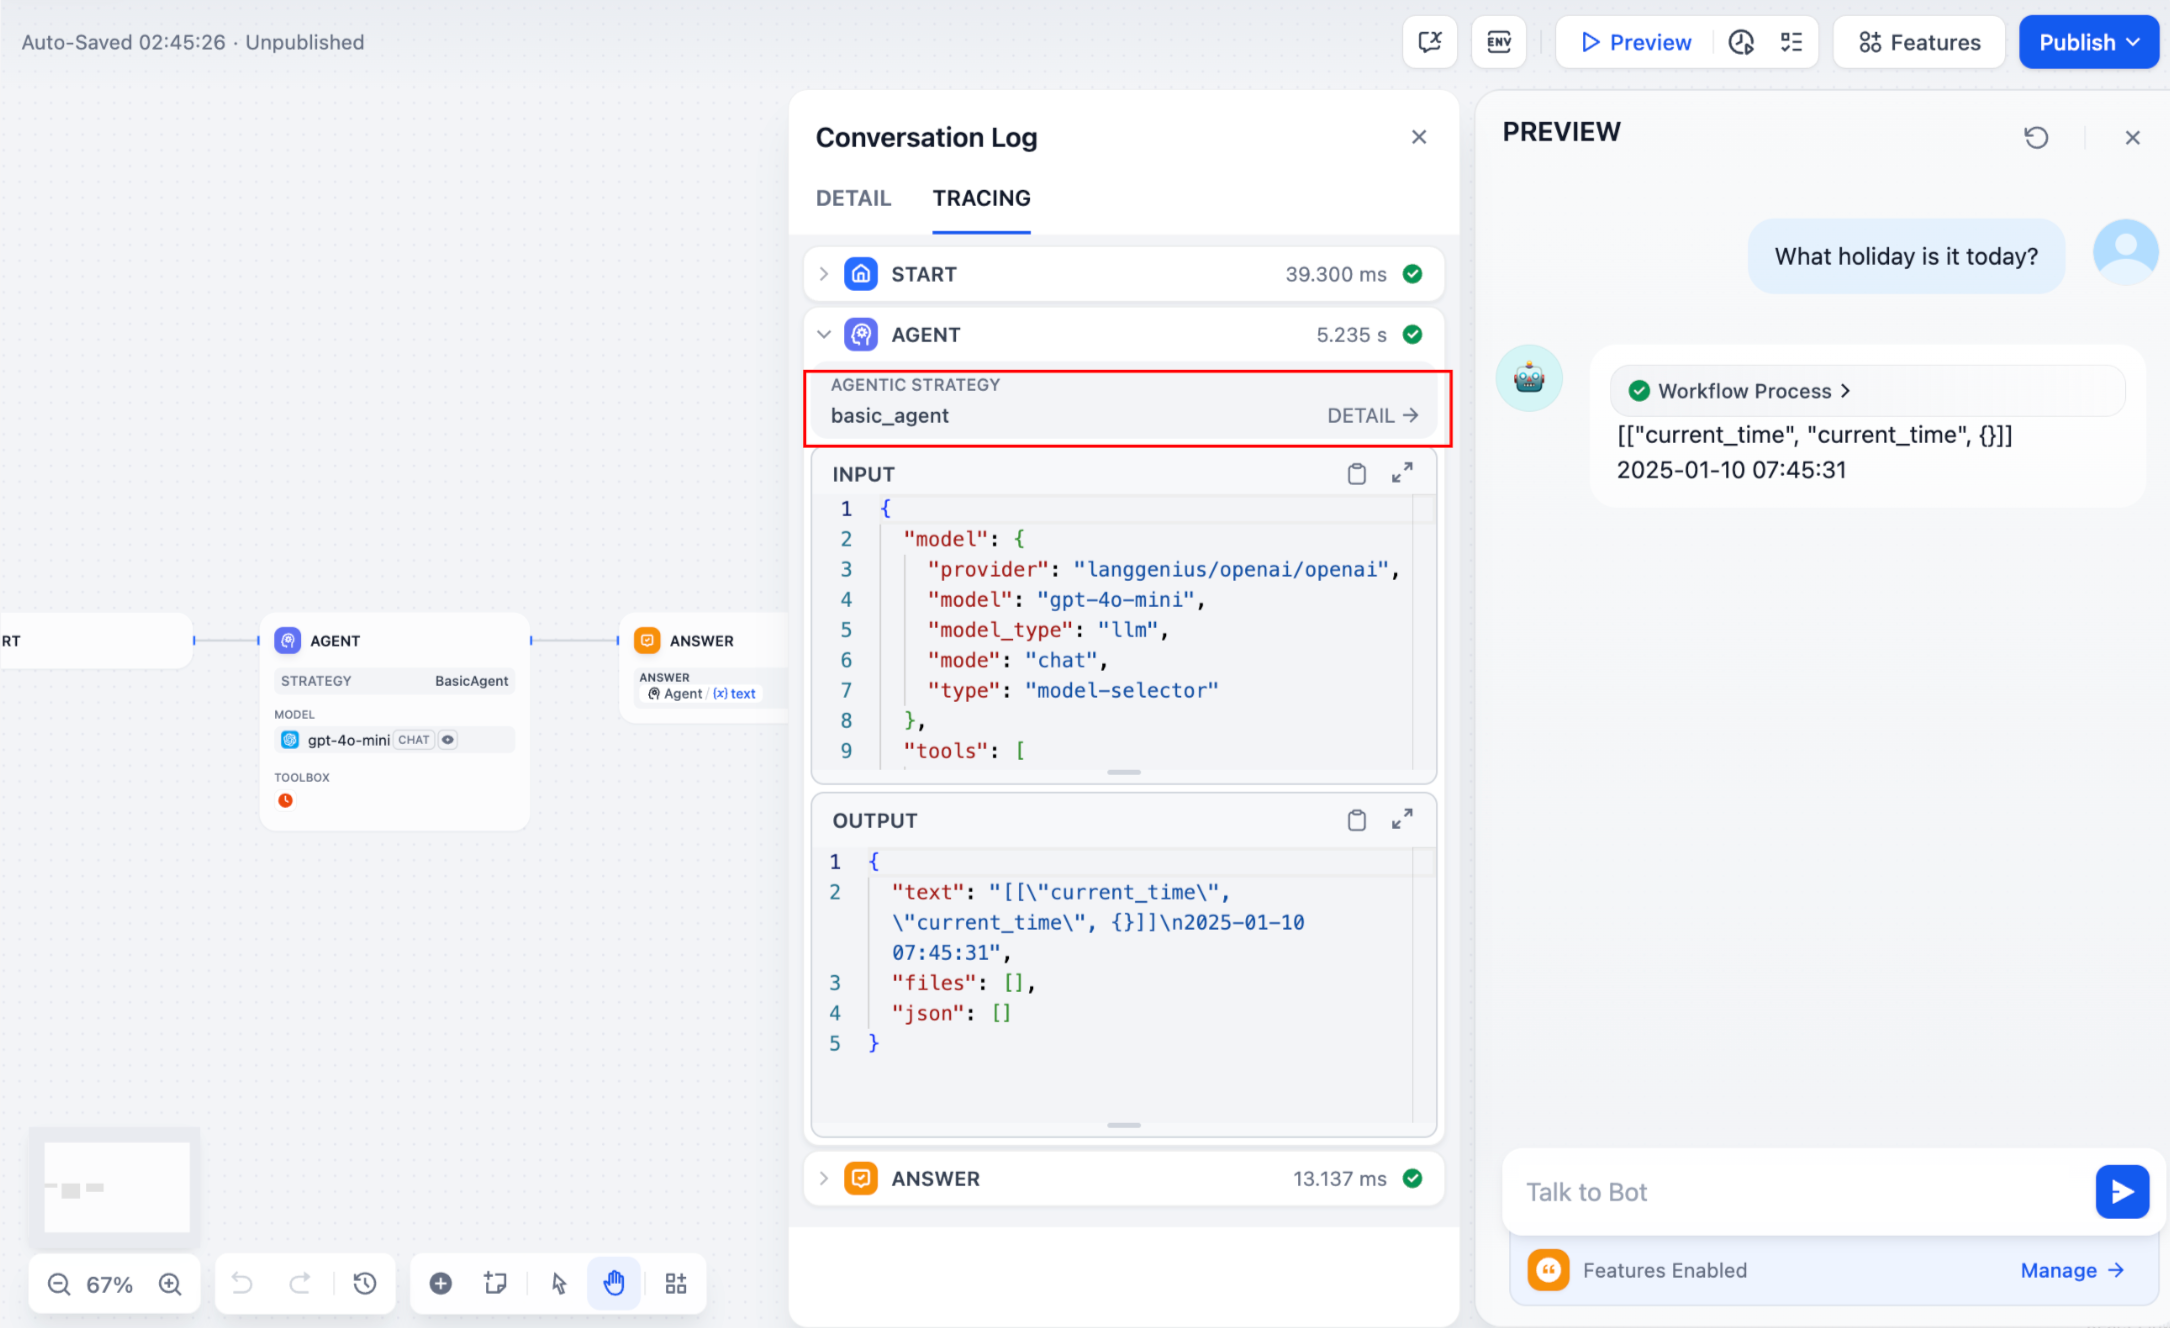
When a task spans multiple rounds, set the parent parameter in your log calls to nest the logs hierarchically and keep them easy to follow:
function_call_round_log = self.create_log_message( label="Function Call Round1 ", data={}, metadata={},)yield function_call_round_logmodel_log = self.create_log_message( label=f"{params.model.model} Thought", data={}, metadata={"start_at": model_started_at, "provider": params.model.provider}, status=ToolInvokeMessage.LogMessage.LogStatus.START, # add parent log parent=function_call_round_log,)yield model_logSample Code#
The following code gives the Agent strategy plugin the ability to invoke the model:
import jsonfrom collections.abc import Generatorfrom typing import Any, castfrom dify_plugin.entities.agent import AgentInvokeMessagefrom dify_plugin.entities.model.llm import LLMModelConfig, LLMResult, LLMResultChunkfrom dify_plugin.entities.model.message import ( PromptMessageTool, UserPromptMessage,)from dify_plugin.entities.tool import ToolInvokeMessage, ToolParameter, ToolProviderTypefrom dify_plugin.interfaces.agent import AgentModelConfig, AgentStrategy, ToolEntityfrom pydantic import BaseModelclass BasicParams(BaseModel): maximum_iterations: int model: AgentModelConfig tools: list[ToolEntity] query: strclass BasicAgentAgentStrategy(AgentStrategy): def _invoke(self, parameters: dict[str, Any]) -> Generator[AgentInvokeMessage]: params = BasicParams(**parameters) chunks: Generator[LLMResultChunk, None, None] | LLMResult = ( self.session.model.llm.invoke( model_config=LLMModelConfig(**params.model.model_dump(mode="json")), prompt_messages=[UserPromptMessage(content=params.query)], tools=[ self._convert_tool_to_prompt_message_tool(tool) for tool in params.tools ], stop=params.model.completion_params.get("stop", []) if params.model.completion_params else [], stream=True, ) ) response = "" tool_calls = [] tool_instances = ( {tool.identity.name: tool for tool in params.tools} if params.tools else {} ) for chunk in chunks: # check if there is any tool call if self.check_tool_calls(chunk): tool_calls = self.extract_tool_calls(chunk) tool_call_names = ";".join([tool_call[1] for tool_call in tool_calls]) try: tool_call_inputs = json.dumps( {tool_call[1]: tool_call[2] for tool_call in tool_calls}, ensure_ascii=False, ) except json.JSONDecodeError: # ensure ascii to avoid encoding error tool_call_inputs = json.dumps( {tool_call[1]: tool_call[2] for tool_call in tool_calls} ) print(tool_call_names, tool_call_inputs) if chunk.delta.message and chunk.delta.message.content: if isinstance(chunk.delta.message.content, list): for content in chunk.delta.message.content: response += content.data print(content.data, end="", flush=True) else: response += str(chunk.delta.message.content) print(str(chunk.delta.message.content), end="", flush=True) if chunk.delta.usage: # usage of the model usage = chunk.delta.usage yield self.create_text_message( text=f"{response or json.dumps(tool_calls, ensure_ascii=False)}\n" ) result = "" for tool_call_id, tool_call_name, tool_call_args in tool_calls: tool_instance = tool_instances[tool_call_name] tool_invoke_responses = self.session.tool.invoke( provider_type=ToolProviderType.BUILT_IN, provider=tool_instance.identity.provider, tool_name=tool_instance.identity.name, parameters={**tool_instance.runtime_parameters, **tool_call_args}, ) if not tool_instance: tool_invoke_responses = { "tool_call_id": tool_call_id, "tool_call_name": tool_call_name, "tool_response": f"there is not a tool named {tool_call_name}", } else: # invoke tool tool_invoke_responses = self.session.tool.invoke( provider_type=ToolProviderType.BUILT_IN, provider=tool_instance.identity.provider, tool_name=tool_instance.identity.name, parameters={**tool_instance.runtime_parameters, **tool_call_args}, ) result = "" for tool_invoke_response in tool_invoke_responses: if tool_invoke_response.type == ToolInvokeMessage.MessageType.TEXT: result += cast( ToolInvokeMessage.TextMessage, tool_invoke_response.message ).text elif ( tool_invoke_response.type == ToolInvokeMessage.MessageType.LINK ): result += ( f"result link: {cast(ToolInvokeMessage.TextMessage, tool_invoke_response.message).text}." + " please tell user to check it." ) elif tool_invoke_response.type in { ToolInvokeMessage.MessageType.IMAGE_LINK, ToolInvokeMessage.MessageType.IMAGE, }: result += ( "image has been created and sent to user already, " + "you do not need to create it, just tell the user to check it now." ) elif ( tool_invoke_response.type == ToolInvokeMessage.MessageType.JSON ): text = json.dumps( cast( ToolInvokeMessage.JsonMessage, tool_invoke_response.message, ).json_object, ensure_ascii=False, ) result += f"tool response: {text}." else: result += f"tool response: {tool_invoke_response.message!r}." tool_response = { "tool_call_id": tool_call_id, "tool_call_name": tool_call_name, "tool_response": result, } yield self.create_text_message(result) def _convert_tool_to_prompt_message_tool( self, tool: ToolEntity ) -> PromptMessageTool: """ convert tool to prompt message tool """ message_tool = PromptMessageTool( name=tool.identity.name, description=tool.description.llm if tool.description else "", parameters={ "type": "object", "properties": {}, "required": [], }, ) parameters = tool.parameters for parameter in parameters: if parameter.form != ToolParameter.ToolParameterForm.LLM: continue parameter_type = parameter.type if parameter.type in { ToolParameter.ToolParameterType.FILE, ToolParameter.ToolParameterType.FILES, }: continue enum = [] if parameter.type == ToolParameter.ToolParameterType.SELECT: enum = ( [option.value for option in parameter.options] if parameter.options else [] ) message_tool.parameters["properties"][parameter.name] = { "type": parameter_type, "description": parameter.llm_description or "", } if len(enum) > 0: message_tool.parameters["properties"][parameter.name]["enum"] = enum if parameter.required: message_tool.parameters["required"].append(parameter.name) return message_tool def check_tool_calls(self, llm_result_chunk: LLMResultChunk) -> bool: """ Check if there is any tool call in llm result chunk """ return bool(llm_result_chunk.delta.message.tool_calls) def extract_tool_calls( self, llm_result_chunk: LLMResultChunk ) -> list[tuple[str, str, dict[str, Any]]]: """ Extract tool calls from llm result chunk Returns: List[Tuple[str, str, Dict[str, Any]]]: [(tool_call_id, tool_call_name, tool_call_args)] """ tool_calls = [] for prompt_message in llm_result_chunk.delta.message.tool_calls: args = {} if prompt_message.function.arguments != "": args = json.loads(prompt_message.function.arguments) tool_calls.append( ( prompt_message.id, prompt_message.function.name, args, ) ) return tool_callsThe following code invokes the model and sends well-formed requests to the tools it selects:
import jsonfrom collections.abc import Generatorfrom typing import Any, castfrom dify_plugin.entities.agent import AgentInvokeMessagefrom dify_plugin.entities.model.llm import LLMModelConfig, LLMResult, LLMResultChunkfrom dify_plugin.entities.model.message import ( PromptMessageTool, UserPromptMessage,)from dify_plugin.entities.tool import ToolInvokeMessage, ToolParameter, ToolProviderTypefrom dify_plugin.interfaces.agent import AgentModelConfig, AgentStrategy, ToolEntityfrom pydantic import BaseModelclass BasicParams(BaseModel): maximum_iterations: int model: AgentModelConfig tools: list[ToolEntity] query: strclass BasicAgentAgentStrategy(AgentStrategy): def _invoke(self, parameters: dict[str, Any]) -> Generator[AgentInvokeMessage]: params = BasicParams(**parameters) chunks: Generator[LLMResultChunk, None, None] | LLMResult = ( self.session.model.llm.invoke( model_config=LLMModelConfig(**params.model.model_dump(mode="json")), prompt_messages=[UserPromptMessage(content=params.query)], tools=[ self._convert_tool_to_prompt_message_tool(tool) for tool in params.tools ], stop=params.model.completion_params.get("stop", []) if params.model.completion_params else [], stream=True, ) ) response = "" tool_calls = [] tool_instances = ( {tool.identity.name: tool for tool in params.tools} if params.tools else {} ) for chunk in chunks: # check if there is any tool call if self.check_tool_calls(chunk): tool_calls = self.extract_tool_calls(chunk) tool_call_names = ";".join([tool_call[1] for tool_call in tool_calls]) try: tool_call_inputs = json.dumps( {tool_call[1]: tool_call[2] for tool_call in tool_calls}, ensure_ascii=False, ) except json.JSONDecodeError: # ensure ascii to avoid encoding error tool_call_inputs = json.dumps( {tool_call[1]: tool_call[2] for tool_call in tool_calls} ) print(tool_call_names, tool_call_inputs) if chunk.delta.message and chunk.delta.message.content: if isinstance(chunk.delta.message.content, list): for content in chunk.delta.message.content: response += content.data print(content.data, end="", flush=True) else: response += str(chunk.delta.message.content) print(str(chunk.delta.message.content), end="", flush=True) if chunk.delta.usage: # usage of the model usage = chunk.delta.usage yield self.create_text_message( text=f"{response or json.dumps(tool_calls, ensure_ascii=False)}\n" ) result = "" for tool_call_id, tool_call_name, tool_call_args in tool_calls: tool_instance = tool_instances[tool_call_name] tool_invoke_responses = self.session.tool.invoke( provider_type=ToolProviderType.BUILT_IN, provider=tool_instance.identity.provider, tool_name=tool_instance.identity.name, parameters={**tool_instance.runtime_parameters, **tool_call_args}, ) if not tool_instance: tool_invoke_responses = { "tool_call_id": tool_call_id, "tool_call_name": tool_call_name, "tool_response": f"there is not a tool named {tool_call_name}", } else: # invoke tool tool_invoke_responses = self.session.tool.invoke( provider_type=ToolProviderType.BUILT_IN, provider=tool_instance.identity.provider, tool_name=tool_instance.identity.name, parameters={**tool_instance.runtime_parameters, **tool_call_args}, ) result = "" for tool_invoke_response in tool_invoke_responses: if tool_invoke_response.type == ToolInvokeMessage.MessageType.TEXT: result += cast( ToolInvokeMessage.TextMessage, tool_invoke_response.message ).text elif ( tool_invoke_response.type == ToolInvokeMessage.MessageType.LINK ): result += ( f"result link: {cast(ToolInvokeMessage.TextMessage, tool_invoke_response.message).text}." + " please tell user to check it." ) elif tool_invoke_response.type in { ToolInvokeMessage.MessageType.IMAGE_LINK, ToolInvokeMessage.MessageType.IMAGE, }: result += ( "image has been created and sent to user already, " + "you do not need to create it, just tell the user to check it now." ) elif ( tool_invoke_response.type == ToolInvokeMessage.MessageType.JSON ): text = json.dumps( cast( ToolInvokeMessage.JsonMessage, tool_invoke_response.message, ).json_object, ensure_ascii=False, ) result += f"tool response: {text}." else: result += f"tool response: {tool_invoke_response.message!r}." tool_response = { "tool_call_id": tool_call_id, "tool_call_name": tool_call_name, "tool_response": result, } yield self.create_text_message(result) def _convert_tool_to_prompt_message_tool( self, tool: ToolEntity ) -> PromptMessageTool: """ convert tool to prompt message tool """ message_tool = PromptMessageTool( name=tool.identity.name, description=tool.description.llm if tool.description else "", parameters={ "type": "object", "properties": {}, "required": [], }, ) parameters = tool.parameters for parameter in parameters: if parameter.form != ToolParameter.ToolParameterForm.LLM: continue parameter_type = parameter.type if parameter.type in { ToolParameter.ToolParameterType.FILE, ToolParameter.ToolParameterType.FILES, }: continue enum = [] if parameter.type == ToolParameter.ToolParameterType.SELECT: enum = ( [option.value for option in parameter.options] if parameter.options else [] ) message_tool.parameters["properties"][parameter.name] = { "type": parameter_type, "description": parameter.llm_description or "", } if len(enum) > 0: message_tool.parameters["properties"][parameter.name]["enum"] = enum if parameter.required: message_tool.parameters["required"].append(parameter.name) return message_tool def check_tool_calls(self, llm_result_chunk: LLMResultChunk) -> bool: """ Check if there is any tool call in llm result chunk """ return bool(llm_result_chunk.delta.message.tool_calls) def extract_tool_calls( self, llm_result_chunk: LLMResultChunk ) -> list[tuple[str, str, dict[str, Any]]]: """ Extract tool calls from llm result chunk Returns: List[Tuple[str, str, Dict[str, Any]]]: [(tool_call_id, tool_call_name, tool_call_args)] """ tool_calls = [] for prompt_message in llm_result_chunk.delta.message.tool_calls: args = {} if prompt_message.function.arguments != "": args = json.loads(prompt_message.function.arguments) tool_calls.append( ( prompt_message.id, prompt_message.function.name, args, ) ) return tool_callsA complete sample that covers model invocation, tool handling, and multi-round logging:
import jsonimport timefrom collections.abc import Generatorfrom typing import Any, castfrom dify_plugin.entities.agent import AgentInvokeMessagefrom dify_plugin.entities.model.llm import LLMModelConfig, LLMResult, LLMResultChunkfrom dify_plugin.entities.model.message import ( PromptMessageTool, UserPromptMessage,)from dify_plugin.entities.tool import ToolInvokeMessage, ToolParameter, ToolProviderTypefrom dify_plugin.interfaces.agent import AgentModelConfig, AgentStrategy, ToolEntityfrom pydantic import BaseModelclass BasicParams(BaseModel): maximum_iterations: int model: AgentModelConfig tools: list[ToolEntity] query: strclass BasicAgentAgentStrategy(AgentStrategy): def _invoke(self, parameters: dict[str, Any]) -> Generator[AgentInvokeMessage]: params = BasicParams(**parameters) function_call_round_log = self.create_log_message( label="Function Call Round1 ", data={}, metadata={}, ) yield function_call_round_log model_started_at = time.perf_counter() model_log = self.create_log_message( label=f"{params.model.model} Thought", data={}, metadata={"start_at": model_started_at, "provider": params.model.provider}, status=ToolInvokeMessage.LogMessage.LogStatus.START, parent=function_call_round_log, ) yield model_log chunks: Generator[LLMResultChunk, None, None] | LLMResult = ( self.session.model.llm.invoke( model_config=LLMModelConfig(**params.model.model_dump(mode="json")), prompt_messages=[UserPromptMessage(content=params.query)], tools=[ self._convert_tool_to_prompt_message_tool(tool) for tool in params.tools ], stop=params.model.completion_params.get("stop", []) if params.model.completion_params else [], stream=True, ) ) response = "" tool_calls = [] tool_instances = ( {tool.identity.name: tool for tool in params.tools} if params.tools else {} ) tool_call_names = "" tool_call_inputs = "" for chunk in chunks: # check if there is any tool call if self.check_tool_calls(chunk): tool_calls = self.extract_tool_calls(chunk) tool_call_names = ";".join([tool_call[1] for tool_call in tool_calls]) try: tool_call_inputs = json.dumps( {tool_call[1]: tool_call[2] for tool_call in tool_calls}, ensure_ascii=False, ) except json.JSONDecodeError: # ensure ascii to avoid encoding error tool_call_inputs = json.dumps( {tool_call[1]: tool_call[2] for tool_call in tool_calls} ) print(tool_call_names, tool_call_inputs) if chunk.delta.message and chunk.delta.message.content: if isinstance(chunk.delta.message.content, list): for content in chunk.delta.message.content: response += content.data print(content.data, end="", flush=True) else: response += str(chunk.delta.message.content) print(str(chunk.delta.message.content), end="", flush=True) if chunk.delta.usage: # usage of the model usage = chunk.delta.usage yield self.finish_log_message( log=model_log, data={ "output": response, "tool_name": tool_call_names, "tool_input": tool_call_inputs, }, metadata={ "started_at": model_started_at, "finished_at": time.perf_counter(), "elapsed_time": time.perf_counter() - model_started_at, "provider": params.model.provider, }, ) yield self.create_text_message( text=f"{response or json.dumps(tool_calls, ensure_ascii=False)}\n" ) result = "" for tool_call_id, tool_call_name, tool_call_args in tool_calls: tool_instance = tool_instances[tool_call_name] tool_invoke_responses = self.session.tool.invoke( provider_type=ToolProviderType.BUILT_IN, provider=tool_instance.identity.provider, tool_name=tool_instance.identity.name, parameters={**tool_instance.runtime_parameters, **tool_call_args}, ) if not tool_instance: tool_invoke_responses = { "tool_call_id": tool_call_id, "tool_call_name": tool_call_name, "tool_response": f"there is not a tool named {tool_call_name}", } else: # invoke tool tool_invoke_responses = self.session.tool.invoke( provider_type=ToolProviderType.BUILT_IN, provider=tool_instance.identity.provider, tool_name=tool_instance.identity.name, parameters={**tool_instance.runtime_parameters, **tool_call_args}, ) result = "" for tool_invoke_response in tool_invoke_responses: if tool_invoke_response.type == ToolInvokeMessage.MessageType.TEXT: result += cast( ToolInvokeMessage.TextMessage, tool_invoke_response.message ).text elif ( tool_invoke_response.type == ToolInvokeMessage.MessageType.LINK ): result += ( f"result link: {cast(ToolInvokeMessage.TextMessage, tool_invoke_response.message).text}." + " please tell user to check it." ) elif tool_invoke_response.type in { ToolInvokeMessage.MessageType.IMAGE_LINK, ToolInvokeMessage.MessageType.IMAGE, }: result += ( "image has been created and sent to user already, " + "you do not need to create it, just tell the user to check it now." ) elif ( tool_invoke_response.type == ToolInvokeMessage.MessageType.JSON ): text = json.dumps( cast( ToolInvokeMessage.JsonMessage, tool_invoke_response.message, ).json_object, ensure_ascii=False, ) result += f"tool response: {text}." else: result += f"tool response: {tool_invoke_response.message!r}." tool_response = { "tool_call_id": tool_call_id, "tool_call_name": tool_call_name, "tool_response": result, } yield self.create_text_message(result) def _convert_tool_to_prompt_message_tool( self, tool: ToolEntity ) -> PromptMessageTool: """ convert tool to prompt message tool """ message_tool = PromptMessageTool( name=tool.identity.name, description=tool.description.llm if tool.description else "", parameters={ "type": "object", "properties": {}, "required": [], }, ) parameters = tool.parameters for parameter in parameters: if parameter.form != ToolParameter.ToolParameterForm.LLM: continue parameter_type = parameter.type if parameter.type in { ToolParameter.ToolParameterType.FILE, ToolParameter.ToolParameterType.FILES, }: continue enum = [] if parameter.type == ToolParameter.ToolParameterType.SELECT: enum = ( [option.value for option in parameter.options] if parameter.options else [] ) message_tool.parameters["properties"][parameter.name] = { "type": parameter_type, "description": parameter.llm_description or "", } if len(enum) > 0: message_tool.parameters["properties"][parameter.name]["enum"] = enum if parameter.required: message_tool.parameters["required"].append(parameter.name) return message_tool def check_tool_calls(self, llm_result_chunk: LLMResultChunk) -> bool: """ Check if there is any tool call in llm result chunk """ return bool(llm_result_chunk.delta.message.tool_calls) def extract_tool_calls( self, llm_result_chunk: LLMResultChunk ) -> list[tuple[str, str, dict[str, Any]]]: """ Extract tool calls from llm result chunk Returns: List[Tuple[str, str, Dict[str, Any]]]: [(tool_call_id, tool_call_name, tool_call_args)] """ tool_calls = [] for prompt_message in llm_result_chunk.delta.message.tool_calls: args = {} if prompt_message.function.arguments != "": args = json.loads(prompt_message.function.arguments) tool_calls.append( ( prompt_message.id, prompt_message.function.name, args, ) ) return tool_calls6. Debug the Plugin#
With the declaration file and implementation code complete, verify that the plugin runs correctly. Dify supports remote debugging: go to Plugin Management to obtain your debug key and remote server address.
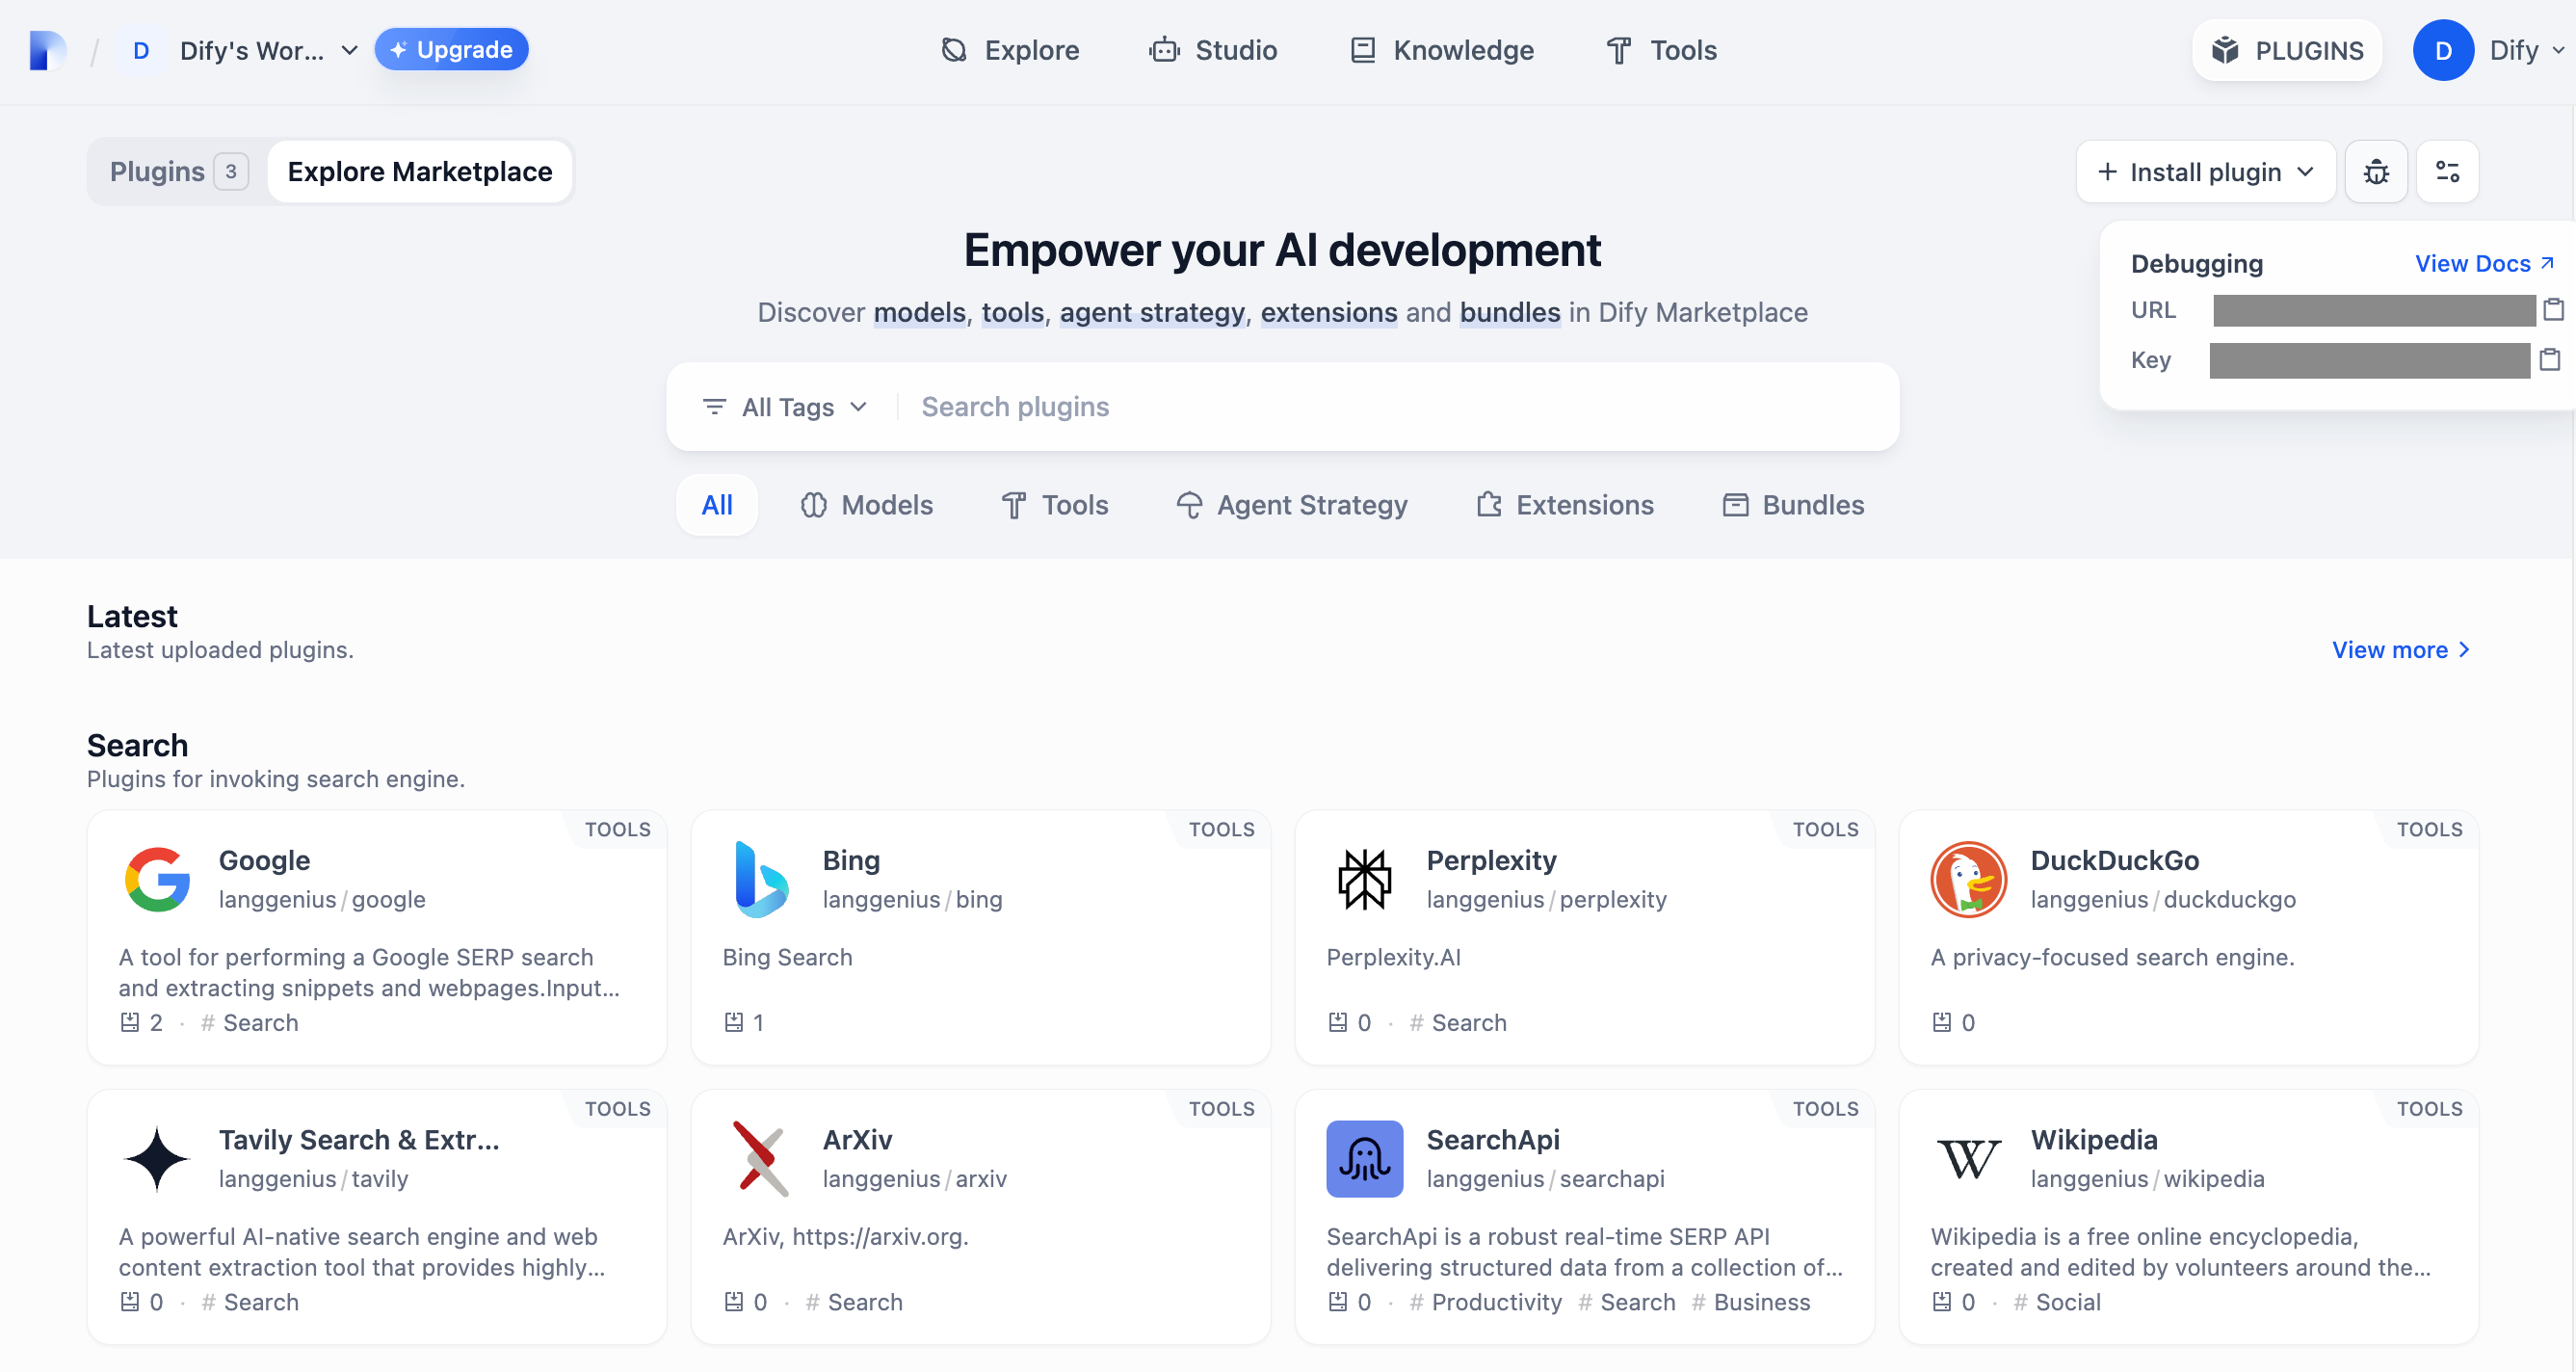
In your plugin project, copy .env.example to .env and fill in the remote server address and debug key.
INSTALL_METHOD=remoteREMOTE_INSTALL_URL=debug.dify.ai:5003REMOTE_INSTALL_KEY=********-****-****-****-************Then run:
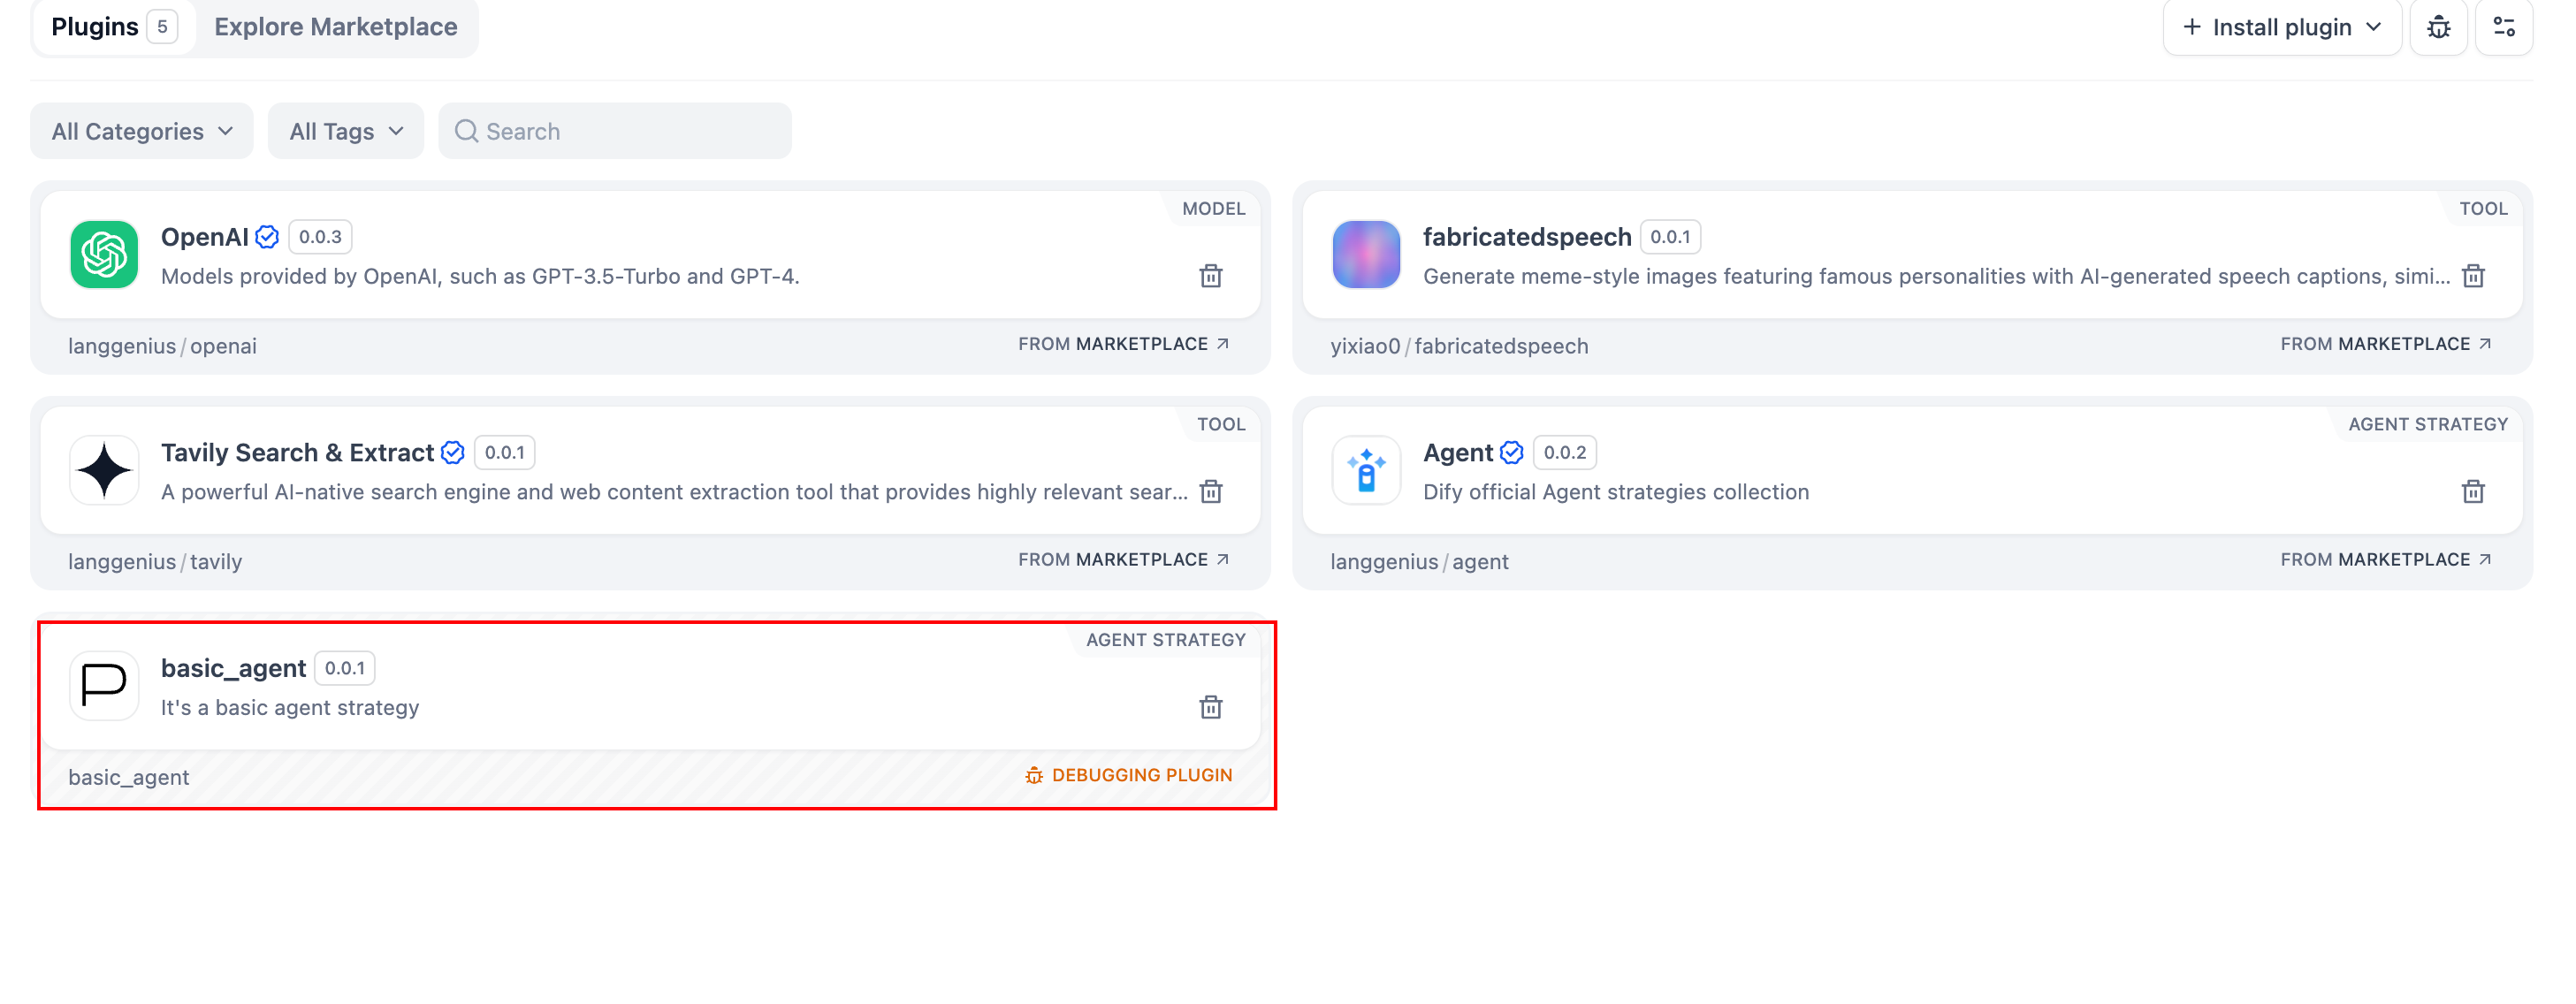
python -m mainThe plugin appears in your workspace, where team members can also access it.
Package the Plugin (Optional)#
Once everything works, package your plugin by running:
# Replace ./basic_agent/ with your actual plugin project path.dify plugin package ./basic_agent/A file named basic_agent.difypkg (matching your plugin name) appears in your current folder. This is your final plugin package.
Congratulations! You’ve developed, tested, and packaged your Agent Strategy Plugin.
Publish the Plugin (Optional)#
You can now submit the package to the Dify Plugins repository. Before doing so, ensure it meets the Marketplace preparation and validation requirements. Once approved, the package merges into the main branch and is released through the Marketplace pipeline.
Further Exploration#
Complex tasks often need multiple rounds of thinking and tool calls, repeating the model invoke → tool use cycle until the task ends or the iteration limit is reached. Managing prompts well is crucial in this process. See the complete Function Calling implementation for a standardized approach to letting models call external tools and handle their outputs.